
Vấn đề
Một trong những thách thức lớn nhất cho nhà khoa học dữ liệu là thu thập dữ liệu. Thực tế có rất nhiều dữ liệu trên web, chỉ cần trích xuất tự động.
Giới thiệu
Mình muốn trích xuất dữ liệu toán tử cơ bản nhúng trong các bảng HTML từ https://www.tutorialspoint.com/python/python_basic_operators.htm.
Dữ liệu rải rác trong nhiều bảng HTML, nếu chỉ có 1 bảng thì copy-paste ra CSV là xong. Nhưng nếu hơn 5 bảng trong một trang thì rất mất thời gian.
Cách thực hiện
1. Tạo file CSV cơ bản
import csv
# Mở file chế độ ghi, không có thì tự tạo
File = open('test.csv', 'w+', newline='', encoding='utf-8')
Data = csv.writer(File)
# Header
Data.writerow(('Column1', 'Column2', 'Column3'))
# Ghi dữ liệu
for i in range(20):
    Data.writerow((i, i+1, i+2))
# Đóng file
File.close()
Kết quả
Mã trên tạo file test.csv trong cùng thư mục.
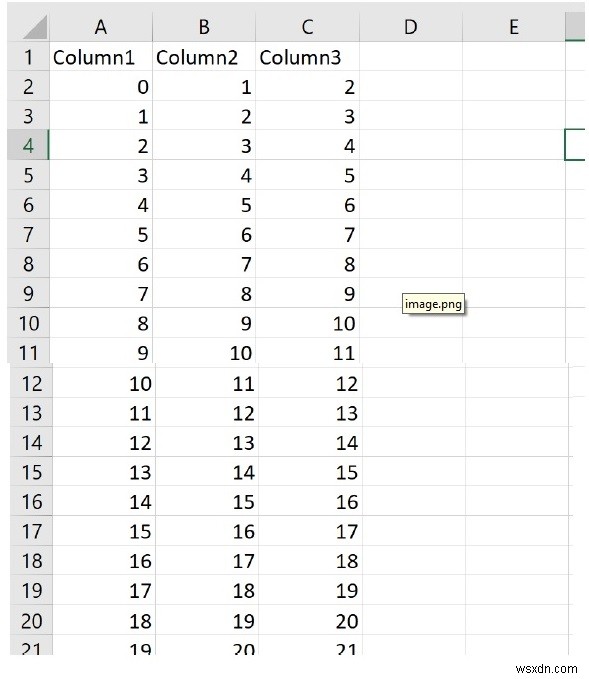
2. Trích xuất bảng HTML và ghi ra CSV
Các import cần thiết:
import csv
from urllib.request import urlopen
from bs4 import BeautifulSoup
url = 'https://www.tutorialspoint.com/python/python_dictionary.htm'
- Mở HTML và lưu vào object html dùng urlopen.
html = urlopen(url)
soup = BeautifulSoup(html, 'html.parser')
- Tìm các bảng trong HTML, lấy dữ liệu bảng đầu tiên [0] để demo.
table = soup.find_all('table')[0]
rows = table.find_all('tr')
print(rows)
[<tr> <th style='text-align:center;width:5%'>Sr.No.</th> <th style='text-align:center;width:95%'>Function with Description</th> </tr>, <tr> <td class='ts'>1</td> <td><a href='/python/dictionary_cmp.htm'>cmp(dict1, dict2)</a> <p>Compares elements of both dict.</p></td> </tr>, ...]
3. Ghi dữ liệu ra file CSV
Ví dụ
File = open('my_html_data_to_csv.csv', 'wt+', newline='', encoding='utf-8')
Data = csv.writer(File)
try:
    for row in rows:
        FilteredRow = []
        for cell in row.find_all(['td', 'th']):
            FilteredRow.append(cell.get_text(strip=True))
        Data.writerow(FilteredRow)
finally:
    File.close()
4. Mã hoàn chỉnh gộp tất cả
import csv
from urllib.request import urlopen
from bs4 import BeautifulSoup

# URL mục tiêu
url = 'https://www.tutorialspoint.com/python/python_basic_syntax.htm'

# Mở URL và parse HTML
html = urlopen(url)
soup = BeautifulSoup(html, 'html.parser')

# Lấy bảng đầu tiên
table = soup.find_all('table')[0]
rows = table.find_all('tr')

# Ghi ra file
File = open('my_html_data_to_csv.csv', 'wt+', newline='', encoding='utf-8')
Data = csv.writer(File)
try:
    for row in rows:
        FilteredRow = []
        for cell in row.find_all(['td', 'th']):
            FilteredRow.append(cell.get_text(strip=True))
        Data.writerow(FilteredRow)
finally:
    File.close()
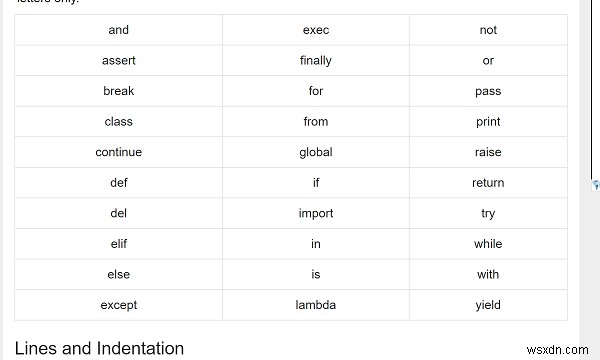
Bảng trong trang HTML
Mẹo: Dùng newline='' và encoding='utf-8' khi open file CSV để tránh dòng trống và lỗi ký tự Unicode. Thư viện pandas cũng cung cấp pd.read_html() để trích xuất bảng nhanh hơn.