
Tôi chưa có con, nhưng khi có, tôi muốn chúng học hai thứ:
- Personal finance (Tài chính cá nhân)
- Machine learning (Học máy)
Dù bạn tin hay không technological singularity gần kề, không thể phủ nhận thế giới chạy trên data. Hiểu data được biến thành knowledge như thế nào là critical cho bất kỳ ai trưởng thành ngày nay — và quan trọng hơn cho developers.
Đây là bài đầu trong series cố gắng làm ML accessible cho full-stack Ruby developers. Bằng cách hiểu ML tools, bạn giúp stakeholders đưa ra quyết định tốt hơn. Bài sau sẽ focus vào techniques và practical examples, bài này set the stage — cho bạn bản đồ và ghim "you are here".
Khởi Đầu Khiêm Tốn
AI và ML không mới. Năm 1950, Arthur Samuel xây chương trình chơi cờ đen. Dùng "alpha-beta pruning" — search algorithm phổ biến.
Anni 1960 thấy multi-layered neural networks và nearest-neighbor algorithm, dùng tìm optimal pathing trong kho.
Nếu AI già vậy, tại sao AI startups lại trendy? Theo tôi, hai lý do:
- Computing power (xem Moore's Law)
- Lượng data thêm vào internet mỗi ngày
Hai thống kê về data tạo ra hàng ngày làm tôi choáng:
- Năm 2018, chúng ta tạo 2.5 quintillion bytes data mỗi ngày. Chắc chắn con số tăng từ khi Forbes đăng bài.
- Hai năm qua, 90% data trên thế giới được generate.
Tức là: (1) hardware lưu data và chạy algorithms ngày càng affordable, (2) data train ML models tăng tốc độ điên rồ.
Mỗi ngày chúng ta interact, bị influence, contribute vào AI/ML world. Ví dụ, thank (hoặc blame) algorithms cho:
- Credit line của bạn
- Chẩn đoán bệnh
- Có thể cả việc bạn có được job hay không
- Tìm route hiệu quả nhất given traffic
- Alexa hiểu bạn khi bạn nói bạn vừa hắt hơi
- Spotify giới thiệu bài hát yêu thích mới
Lý do tôi nhắc đến hypothetical kids: tôi muốn chúng hiểu digital lives ảnh hưởng real lives như thế nào, implications của data privacy decisions, và cách form opinions khi nào trust machine vs không.
Phần còn lại, tôi overview ba loại ML tôi studied: supervised, unsupervised, reinforcement learning. Sẽ nói về uniqueness và problems mỗi loại giải quyết tốt.
Supervised Learning (Học Có Giám Sát)
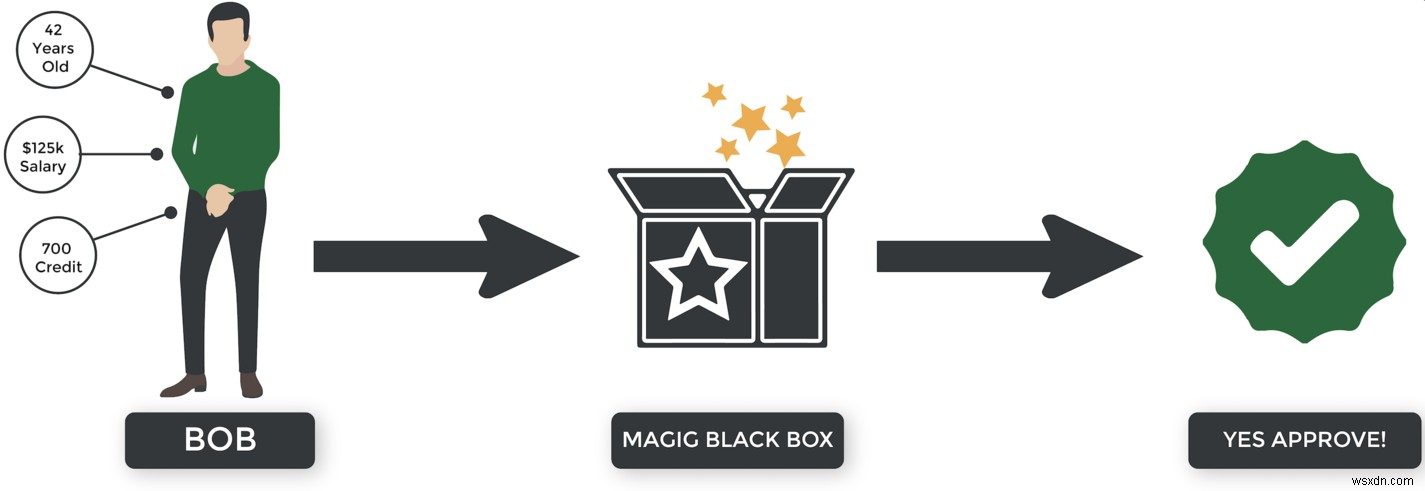
Supervised learning... supervised by humans. :) Hãy tưởng tượng build supervised system quyết định ai được approve mortgage. Có thể hoạt động:
- Bank compile dataset map customer attributes (tuổi, lương, v.v.) đến outcomes (repayment, default, v.v.).
- Train system dùng data.
- System dùng knowledge để guess future outcomes dựa trên attributes của applicant.
- Nếu algorithm guess đúng, bảo "Great job!" Sai thì bảo "No, incorrect. Improve và try again."
Ví dụ này là "classification" problem vì output là category — approved hoặc không. Classification problems khác:
- Người có bệnh hay không
- X-ray có gãy xương hay không
- Email có phải spam không
Muốn biết math behind ML classification algorithms, Google: naive Bayes classifiers, support vector machines, logistic regression, neural networks, random forests.
Ngoài classification (yes/no), supervised learning cũng solve regression problems — prediction trên continuous scale:
- Giá trị tương lai của stock
- Xác suất New England Patriots win Super Bowl
- Average salary company cần offer candidate để accept
Algorithms cho supervised regression: linear regression, non-linear regression, Bayesian linear regression.
Unsupervised Learning (Học Không Giám Sát)
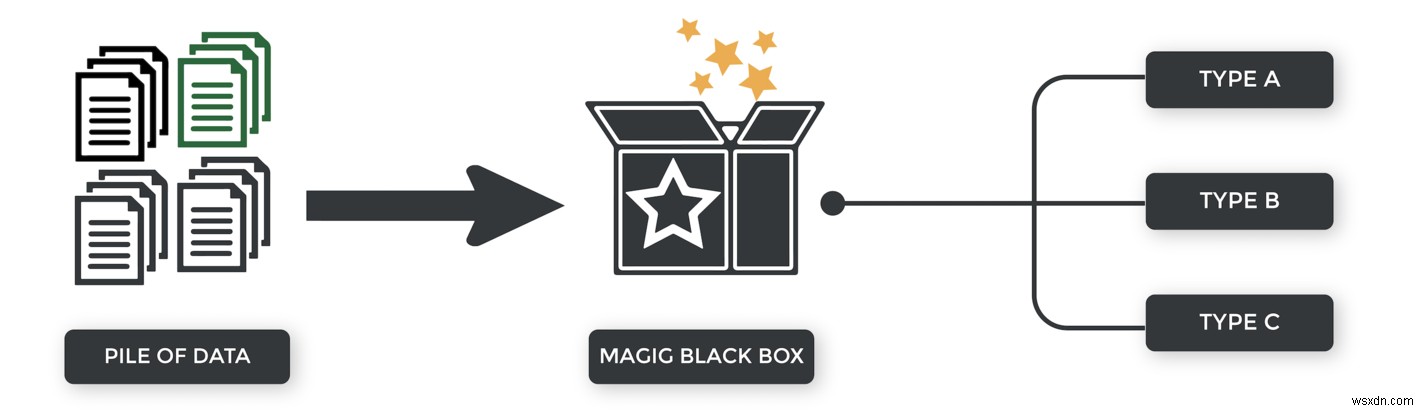
Với supervised, chúng ta predefined categories. Mortgage applicant hoặc approved hoặc denied.
Với unsupervised, chúng ta KHÔNG cung cấp categories. Chúng không available. Algorithm phải tự kết luận.
Tại sao dùng unsupervised?
1) Đôi khi không biết categories trước. Nhiều data trên internet unstructured — thiếu labels.
2) Đôi khi không biết tìm gì, nhờ algorithm tìm patterns/features useful cho categorization.
Cách khác handle unstructured data với ML: nhờ humans manually label. Nhiều companies hire workers classify data: labeling data.
Các Cách Tiếp Cận Unsupervised Learning
Hai techniques phổ biến: association và clustering.
Association: Hãy tưởng tượng bạn Amazon. Bạn có customer data, purchase history. Dùng unsupervised, partition customers thành "types of shoppers" — ví dụ mua pink umbrellas thì likely mua Matcha tea.
Clustering: Clustering nhìn data partition vào số groups/clusters chỉ định. Ví dụ: housing data, tìm features (crime data?) predict neighborhood. Hoặc cosine similarity cho text classification (bài này về tennis, cooking, hay space?).
Muốn học thêm techniques, Google: k-means clustering, cosine similarity, hierarchical clustering, k-nearest-neighbor clustering.
Reinforcement Learning (Học Tăng Cường)
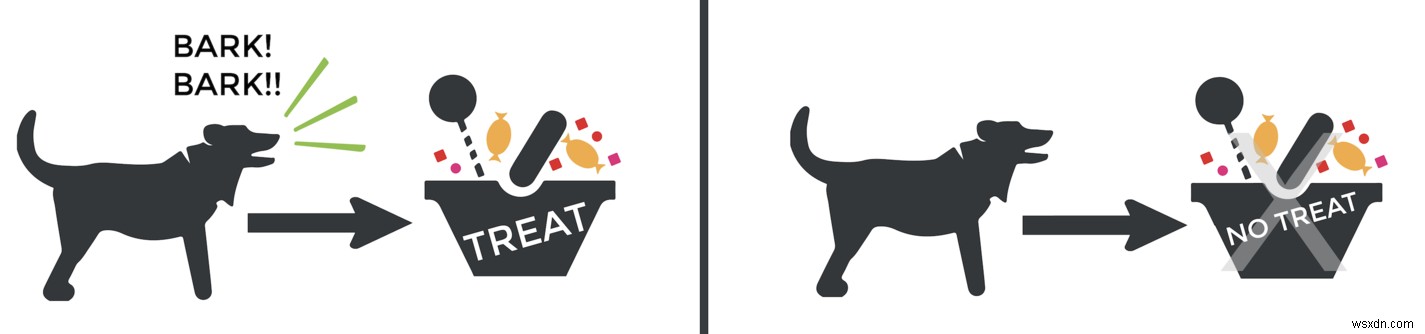
Subset ML này dùng trong games vì dùng goal-oriented algorithms. Khác supervised, mỗi decision KHÔNG independent — given current input, algorithm decide và next input depends on this decision.
Giống như tôi vỗ đầu chó khi nó ngừng sủa khi chuông reo hoặc cho vào chuồng khi nó không ngừng, reinforcement algorithms được reward khi decision optimize goal (ví dụ max points) và penalized khi decision tồi.
Applications rõ ràng:
- Games như chess, Go (khuyên AlphaGo documentary trên Netflix nếu chưa xem)
- Robotics (dạy bots complete tasks)
- Autonomous vehicles
- Robo-advisors trained beat stock market
Muốn học algorithms behind reinforcement learning, Google: Q-learning, state-action-reward-state-action (SARSA), DQN, asynchronous advantage actor critic.
Kết Luận
Hy vọng examples giúp bạn nắm ML techniques và cách mỗi loại influence thế giới điên rồ này. Tôi thỉnh thoảng overwhelmed với lượng knowledge, nhưng bắt đầu đâu đó tốt hơn không làm gì. Nhớ rằng nhiều thứ này không mới — chúng ta chỉ nghe nhiều hơn khi data available hơn và processing power rẻ hơn.