
Từ xây dựng Convolutional Neural Network đến triển khai OCR lên iOS
Động Lực Của Dự Án ✍️
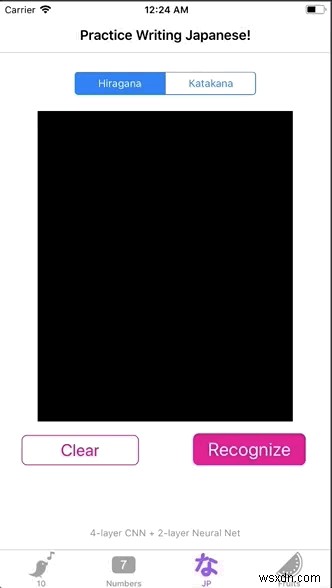
Khi học cách tạo mô hình deep learning cho dataset MNIST vài tháng trước, tôi cuối cùng đã tạo được ứng dụng iOS nhận diện chữ viết tay.
Bạn Kaichi Momose đang phát triển app học tiếng Nhật Nukon. Anh ấy tình cờ muốn tính năng tương tự. Chúng tôi hợp tác xây dựng thứ tinh vi hơn bộ nhận diện chữ số: OCR (Optical Character Recognition) cho ký tự tiếng Nhật (Hiragana và Katakana).

Trong quá trình phát triển Nukon, không có API nhận diện chữ viết tay tiếng Nhật. Chúng tôi buộc phải tự xây dựng OCR. Lợi ích lớn nhất là hoạt động offline. User có thể ở sâu trong núi không có internet vẫn mở Nukon duy trì thói quen học tiếng Nhật hàng ngày. Chúng tôi học được rất nhiều, nhưng quan trọng hơn, rất hào hứng khi giao sản phẩm tốt hơn cho người dùng.
Bài viết này phân tích quy trình xây dựng Japanese OCR cho app iOS. Ai muốn xây dựng cho ngôn ngữ/ký hiệu khác, hãy tùy chỉnh bằng cách thay đổi dataset.
Nội dung bao gồm:
Phần 1️⃣: Lấy dataset và tiền xử lý ảnh
Phần 2️⃣: Xây dựng & train CNN (Convolutional Neural Network)
Phần 3️⃣: Tích hợp mô hình đã train vào iOS
Lấy Dataset & Tiền Xử Lý Ảnh
Dataset từ ETL Character Database, chứa 9 tập ảnh ký tự và ký hiệu viết tay. Vì xây dựng OCR cho Hiragana, dùng dataset ETL8.
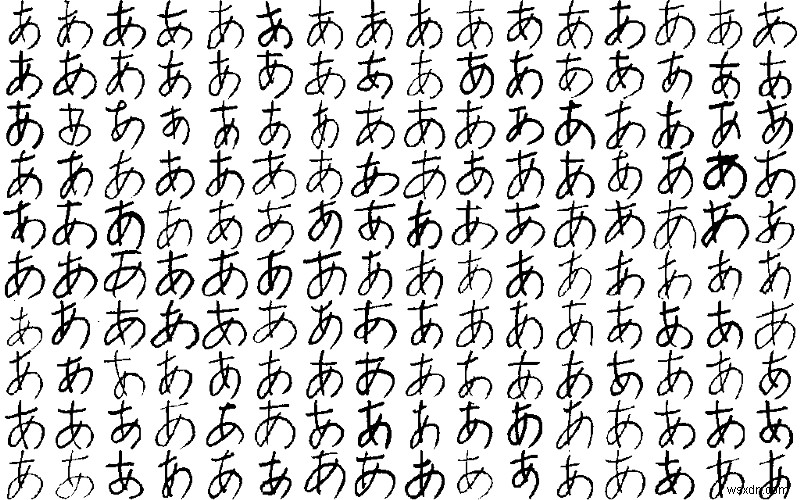
Để lấy ảnh từ database, cần helper function đọc và lưu ảnh dạng .npz.
import struct
import numpy as np
from PIL import Image
sz_record = 8199
def read_record_ETL8G(f):
    s = f.read(sz_record)
    r = struct.unpack('>2H8sI4B4H2B30x8128s11x', s)
    iF = Image.frombytes('F', (128, 127), r[14], 'bit', 4)
    iL = iF.convert('L')
    return r + (iL,)
def read_hiragana():
    # Type of characters = 70, person = 160, y = 127, x = 128
    ary = np.zeros([71, 160, 127, 128], dtype=np.uint8)
    for j in range(1, 33):
        filename = '../../ETL8G/ETL8G_{:02d}'.format(j)
        with open(filename, 'rb') as f:
            for id_dataset in range(5):
                moji = 0
                for i in range(956):
                    r = read_record_ETL8G(f)
                    if b'.HIRA' in r[2] or b'.WO.' in r[2]:
                        if not b'KAI' in r[2] and not b'HEI' in r[2]:
                            ary[moji, (j - 1) * 5 + id_dataset] = np.array(r[-1])
                            moji += 1
    np.savez_compressed("hiragana.npz", ary)
Sau khi có hiragana.npz, bắt đầu xử lý ảnh bằng cách load file và reshape kích thước ảnh thành 32x32 pixel. Cũng thêm data augmentation để sinh ảnh bổ sung xoay và zoom. Khi mô hình train trên ảnh ký tự từ nhiều góc độ, mô hình thích ứng tốt hơn với chữ viết tay.
import scipy.misc
from keras.layers import Conv2D, MaxPooling2D
from keras.layers import Dense, Dropout, Activation, Flatten
from keras.models import Sequential
from keras.preprocessing.image import ImageDataGenerator
from keras.utils import np_utils
from sklearn.model_selection import train_test_split
# 71 ký tự
nb_classes = 71
# Kích thước ảnh đầu vào
img_rows, img_cols = 32, 32
ary = np.load("hiragana.npz")['arr_0'].reshape([-1, 127, 128]).astype(np.float32) / 15
X_train = np.zeros([nb_classes * 160, img_rows, img_cols], dtype=np.float32)
for i in range(nb_classes * 160):
    X_train[i] = scipy.misc.imresize(ary[i], (img_rows, img_cols), mode='F')
y_train = np.repeat(np.arange(nb_classes), 160)
X_train, X_test, y_train, y_test = train_test_split(X_train, y_train, test_size=0.2)
# Chuyển vector class thành ma trận categorical
y_train = np_utils.to_categorical(y_train, nb_classes)
y_test = np_utils.to_categorical(y_test, nb_classes)
# Data augmentation
datagen = ImageDataGenerator(rotation_range=15, zoom_range=0.20)
datagen.fit(X_train)
Xây Dựng Và Train CNN
Phần thú vị! Dùng Keras xây dựng CNN (Convolutional Neural Network) cho mô hình. Khi lần đầu xây dựng, tôi thử nghiệm hyper-parameter và điều chỉnh nhiều lần. Tổ hợp dưới cho độ chính xác cao nhất — 98.77%. Tự do thử tham số khác.
model = Sequential()
def model_6_layers():
    model.add(Conv2D(32, 3, 3, input_shape=input_shape))
    model.add(Activation('relu'))
    model.add(Conv2D(32, 3, 3))
    model.add(Activation('relu'))
    model.add(MaxPooling2D(pool_size=(2, 2)))
    model.add(Dropout(0.5))
    model.add(Conv2D(64, 3, 3))
    model.add(Activation('relu'))
    model.add(Conv2D(64, 3, 3))
    model.add(Activation('relu'))
    model.add(MaxPooling2D(pool_size=(2, 2)))
    model.add(Dropout(0.5))
    model.add(Flatten())
    model.add(Dense(256))
    model.add(Activation('relu'))
    model.add(Dropout(0.5))
    model.add(Dense(nb_classes))
    model.add(Activation('softmax'))
model_6_layers()
model.compile(loss='categorical_crossentropy', optimizer='adam', metrics=['accuracy'])
model.fit_generator(datagen.flow(X_train, y_train, batch_size=16), samples_per_epoch=X_train.shape[0], nb_epoch=30, validation_data=(X_test, y_test))
Mẹo nếu hiệu suất mô hình không đạt yêu cầu ở bước train:
Mô hình overfitting
Nghĩa là mô hình không generalize tốt. Xem bài viết này để giải thích trực quan.
Cách phát hiện overfitting: acc (accuracy) tiếp tục tăng, nhưng val_acc (validation accuracy) giảm trong quá trình train.
Giải pháp overfitting: regularization (vd. dropouts), data augmentation, cải thiện chất lượng dataset
Cách Biết Mô Hình Có "Học" Không
Mô hình không học nếu val_loss (validation loss) tăng hoặc không giảm khi train tiếp.
Dùng TensorBoard — cung cấp visualization hiệu suất mô hình theo thời gian. Loại bỏ việc nhìn từng epoch và so sánh giá trị liên tục.
Khi hài lòng với độ chính xác, xóa dropout layer trước khi lưu trọng số và cấu hình mô hình thành file.
for k in model.layers:
    if type(k) is keras.layers.Dropout:
        model.layers.remove(k)
model.save('hiraganaModel.h5')
Nhiệm vụ cuối trước phần iOS là chuyển hiraganaModel.h5 sang model CoreML.
import coremltools
output_labels = [
    'あ', 'い', 'う', 'え', 'お', 'か', 'く', 'こ', 'し', 'せ', 'た', 'つ', 'と', 'に', 'ね', 'は', 'ふ', 'ほ', 'み', 'め', 'や', 'ゆ', 'よ', 'ら', 'り', 'る', 'わ', 'が', 'げ', 'じ', 'ぞ', 'だ', 'ぢ', 'づ', 'で', 'ど', 'ば', 'び', 'ぶ', 'べ', 'ぼ', 'ぱ', 'ぴ', 'ぷ', 'ぺ', 'ぽ', 'き', 'け', 'さ', 'す', 'そ', 'ち', 'て', 'な', 'ぬ', 'の', 'ひ', 'へ', 'ま', 'む', 'も', 'れ', 'を', 'ぎ', 'ご', 'ず', 'ぜ', 'ん', 'ぐ', 'ざ', 'ろ']
scale = 1/255.
coreml_model = coremltools.converters.keras.convert('./hiraganaModel.h5', input_names='image', image_input_names='image', output_names='output', class_labels=output_labels, image_scale=scale)
coreml_model.author = 'Your Name'
coreml_model.license = 'MIT'
coreml_model.short_description = 'Detect hiragana character from handwriting'
coreml_model.input_description['image'] = 'Grayscale image containing a handwritten character'
coreml_model.output_description['output'] = 'Output a character in hiragana'
coreml_model.save('hiraganaModel.mlmodel')
output_labels là tất cả output có thể thấy trong iOS sau này.
Sự thật thú vị: nếu hiểu tiếng Nhật, bạn biết thứ tự output character không khớp với "thứ tự bảng chữ cái" Hiragana. Tốn thời gian nhận ra ảnh trong ETL8 không theo "thứ tự bảng chữ cái" (cảm ơn Kaichi nhận ra). Dataset do trường đại học Nhật biên soạn…?
Tích Hợp Mô Hình Đã Train Vào iOS
Cuối cùng gộp mọi thứ! Kéo thả hiraganaModel.mlmodel vào project Xcode. Sẽ thấy:
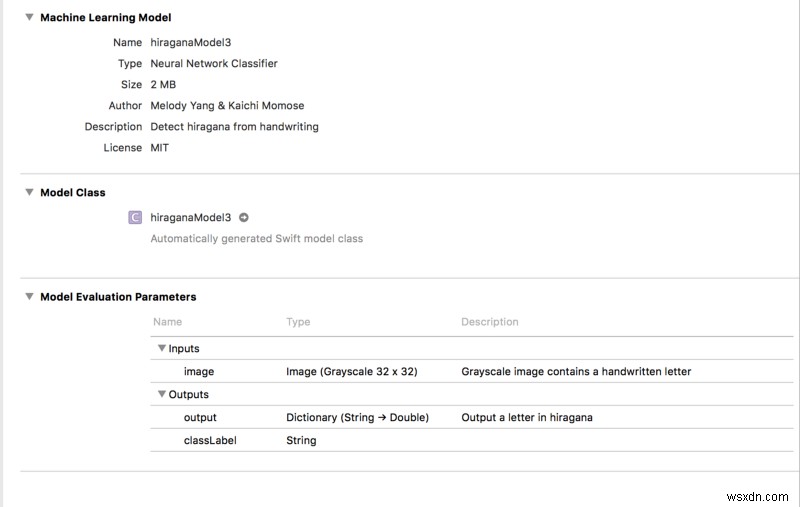
Lưu ý: Xcode tạo workspace khi copy model. Cần chuyển môi trường code sang workspace nếu không model ML không chạy!
Mục tiêu: mô hình Hiragana dự đoán ký tự bằng cách truyền ảnh. Để đạt được, tạo UI đơn giản cho user viết, lưu chữ viết thành format ảnh. Cuối cùng, lấy giá trị pixel của ảnh và đưa vào mô hình.
Làm từng bước:
- "Vẽ" ký tự trên
UIViewvớiUIBezierPath
import UIKit
class ViewController: UIViewController {
    @IBOutlet weak var canvas: UIView!
    var path = UIBezierPath()
    var startPoint = CGPoint()
    var touchPoint = CGPoint()
    override func viewDidLoad() {
        super.viewDidLoad()
        canvas.clipsToBounds = true
        canvas.isMultipleTouchEnabled = true
    }
    override func touchesBegan(_ touches: Set<UITouch>, with event: UIEvent?) {
        let touch = touches.first
        if let point = touch?.location(in: canvas) {
            startPoint = point
        }
    }
    override func touchesMoved(_ touches: Set<UITouch>, with event: UIEvent?) {
        let touch = touches.first
        if let point = touch?.location(in: canvas) {
            touchPoint = point
        }
        path.move(to: startPoint)
        path.addLine(to: touchPoint)
        startPoint = touchPoint
        draw()
    }
    func draw() {
        let strokeLayer = CAShapeLayer()
        strokeLayer.fillColor = nil
        strokeLayer.lineWidth = 8
        strokeLayer.strokeColor = UIColor.orange.cgColor
        strokeLayer.path = path.cgPath
        canvas.layer.addSublayer(strokeLayer)
    }
    // Xóa vẽ trong view
    @IBAction func clearPressed(_ sender: UIButton) {
        path.removeAllPoints()
        canvas.layer.sublayers = nil
        canvas.setNeedsDisplay()
    }
}
strokeLayer.strokeColor có thể bất kỳ màu nào. Tuy nhiên, màu nền của canvas phải là đen. Mặc dù ảnh train có nền đen và nét trắng, mô hình ML không phản ứng tốt với ảnh input kiểu này.
2. Chuyển UIView thành UIImage và lấy giá trị pixel với CVPixelBuffer
Trong extension, có hai helper function. Cùng nhau chuyển ảnh thành pixel buffer, tương đương giá trị pixel. Input width và height đều 32 vì kích thước đầu vào mô hình là 32x32 pixel.
Ngay khi có pixelBuffer, gọi model.prediction() truyền pixelBuffer. Và xong! Có output classLabel!
@IBAction func recognizePressed(_ sender: UIButton) {
    // Chuyển view thành ảnh
    let resultImage = UIImage.init(view: canvas)
    let pixelBuffer = resultImage.pixelBufferGray(width: 32, height: 32)
    let model = hiraganaModel3()
    // Output ký tự Hiragana
    let output = try? model.prediction(image: pixelBuffer!)
    print(output?.classLabel)
}
extension UIImage {
    // Resize ảnh width x height và chuyển thành grayscale CVPixelBuffer
    func pixelBufferGray(width: Int, height: Int) -> CVPixelBuffer? {
        return _pixelBuffer(width: width, height: height, pixelFormatType: kCVPixelFormatType_OneComponent8, colorSpace: CGColorSpaceCreateDeviceGray(), alphaInfo: .none)
    }
    func _pixelBuffer(width: Int, height: Int, pixelFormatType: OSType, colorSpace: CGColorSpace, alphaInfo: CGImageAlphaInfo) -> CVPixelBuffer? {
        var maybePixelBuffer: CVPixelBuffer?
        let attrs = [kCVPixelBufferCGImageCompatibilityKey: kCFBooleanTrue, kCVPixelBufferCGBitmapContextCompatibilityKey: kCFBooleanTrue]
        let status = CVPixelBufferCreate(kCFAllocatorDefault, width, height, pixelFormatType, attrs as CFDictionary, &maybePixelBuffer)
        guard status == kCVReturnSuccess, let pixelBuffer = maybePixelBuffer else { return nil }
        CVPixelBufferLockBaseAddress(pixelBuffer, CVPixelBufferLockFlags(rawValue: 0))
        let pixelData = CVPixelBufferGetBaseAddress(pixelBuffer)
        guard let context = CGContext(data: pixelData, width: width, height: height, bitsPerComponent: 8, bytesPerRow: CVPixelBufferGetBytesPerRow(pixelBuffer), space: colorSpace, bitmapInfo: alphaInfo.rawValue) else { return nil }
        UIGraphicsPushContext(context)
        context.translateBy(x: 0, y: CGFloat(height))
        context.scaleBy(x: 1, y: -1)
        self.draw(in: CGRect(x: 0, y: 0, width: width, height: height))
        UIGraphicsPopContext()
        CVPixelBufferUnlockBaseAddress(pixelBuffer, CVPixelBufferLockFlags(rawValue: 0))
        return pixelBuffer
    }
}
3. Hiển thị output với UIAlertController
Bước này tùy chọn. Như GIF đầu tiên, tôi thêm alert controller thông báo kết quả.
func informResultPopUp(message: String) {
    let alertController = UIAlertController(title: message, message: nil, preferredStyle: .alert)
    let ok = UIAlertAction(title: "Ok", style: .default, handler: { action in self.dismiss(animated: true, completion: nil) })
    alertController.addAction(ok)
    self.present(alertController, animated: true) { () in }
}
Voila! Vừa xây dựng OCR sẵn sàng demo (và sẵn sàng App Store)! 🎉
Kết Luận
Xây dựng OCR không quá khó. Như bạn thấy, bài viết gồm các bước và vấn đề tôi gặp khi xây dựng dự án. Tôi thích quá trình biến bunch Python code thành demo bằng cách kết nối với iOS, và định tiếp tục làm vậy.
Hy vọng bài viết cung cấp thông tin hữu ích cho ai muốn xây dựng OCR nhưng không biết bắt đầu từ đâu.
Tìm source code tại đây.
Bonus: nếu quan tâm thử thuật toán shallow, tiếp tục đọc!
[Tùy chọn] Train Với Thuật Toán Shallow
Trước khi triển khai CNN, Kaichi và tôi test thuật toán ML khác xem có làm được không (và tiết kiệm chi phí compute!). Chọn KNN và Random Forest.
Để đánh giá hiệu suất, định nghĩa baseline accuracy = 1/71 = 0.014.
Giả sử người không biết tiếng Nhật có 1.4% cơ hội đoán đúng ký tự.
Vậy mô hình làm tốt nếu accuracy vượt 1.4%. Xem có không nhé. 🤔
KNN
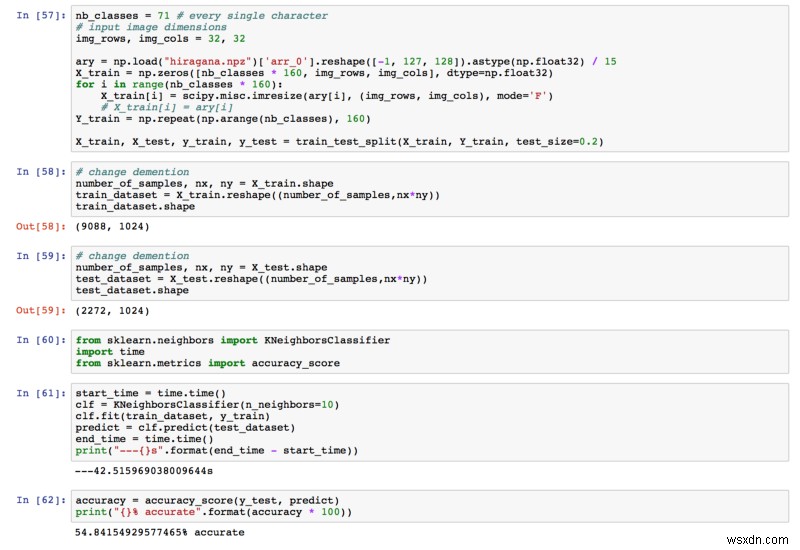
Độ chính xác cuối cùng 54.84%. Cao hơn 1.4% nhiều!
Random Forest
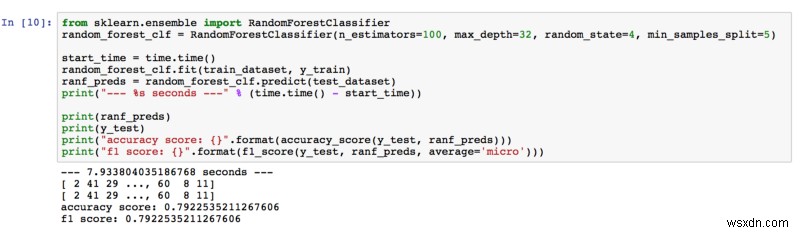
Độ chính xác 79.23%, Random Forest vượt kỳ vọng. Khi tune hyper-parameter, kết quả tốt hơn bằng cách tăng số estimator và độ sâu cây. Nghĩ rằng nhiều cây (estimator) hơn nghĩa là học nhiều feature ảnh hơn. Càng sâu cây, càng học chi tiết từ feature.
Nếu muốn tìm hiểu thêm, tôi tìm thấy paper thảo luận image classification với Random Forest.
Cảm ơn đã đọc. Mọi ý kiến và feedback đều hoan nghênh!