
Giới Thiệu
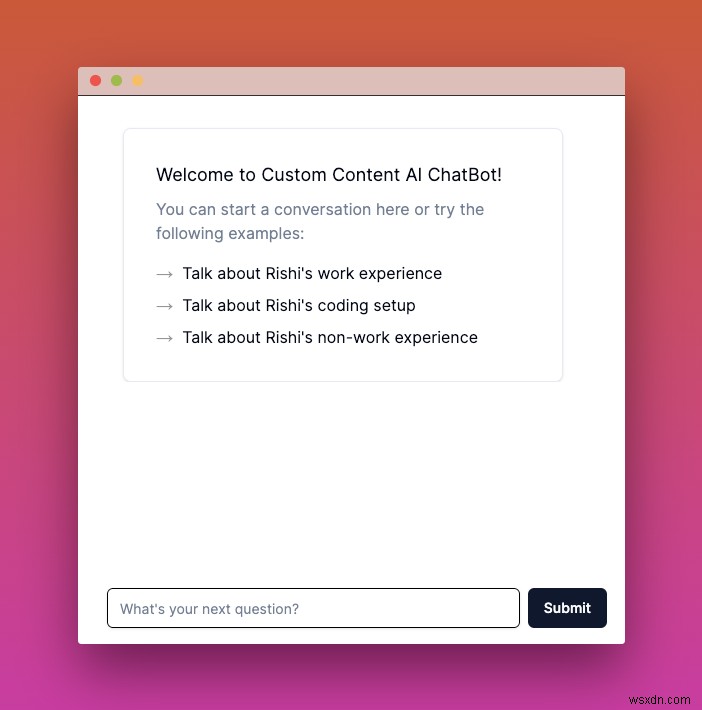
Trong bài viết này, tôi chia sẻ cách xây dựng open-source Custom Content AI Chatbot với Upstash, Next.js, LangChain và Fly.io. Upstash giúp schedule model training, cung cấp rate limiting hào phóng và caching OpenAI API responses.
Công Nghệ Sử Dụng
- Next.js (Front-end và Back-end)
- LangChain (framework phát triển ứng dụng powered by language models)
- Upstash (Scheduling Training Model via QStash, Rate Limiting & Caching OpenAI Responses)
- Tailwind CSS (Styling)
- Fly.io (Deployment)
Yêu Cầu
- Node.js 18
- Tài khoản Upstash
- Tài khoản OpenAI (cho OpenAI API Key)
Thiết Lập Upstash Redis
Đăng nhập Upstash, vào tab Redis tạo database.
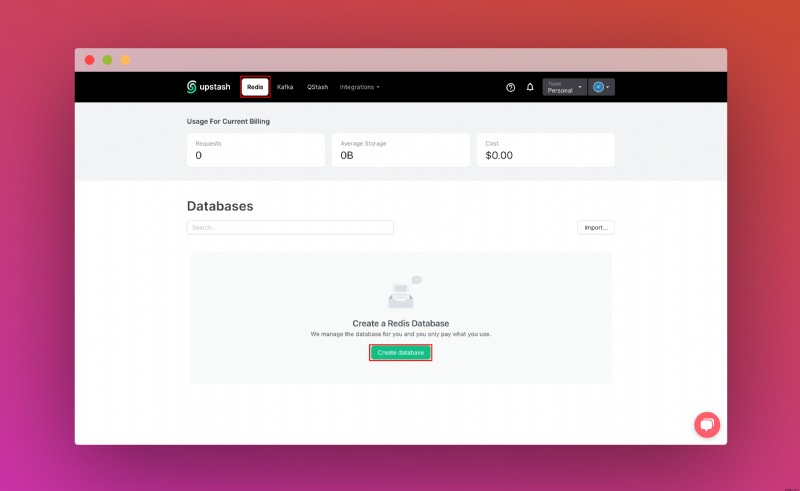
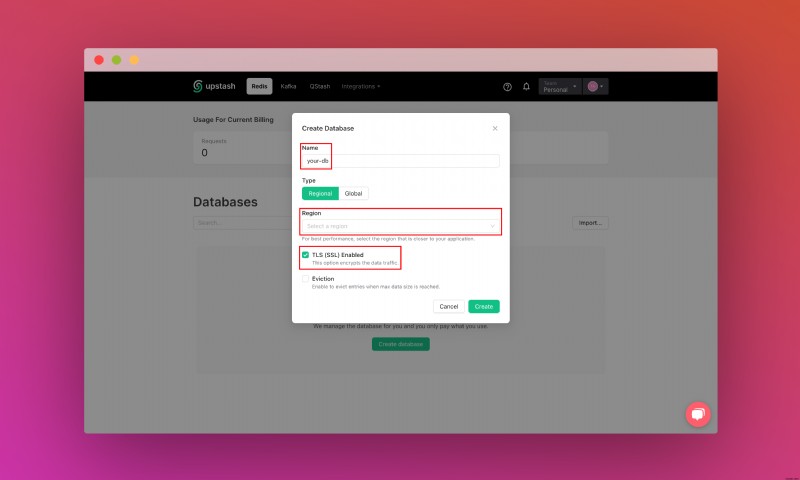
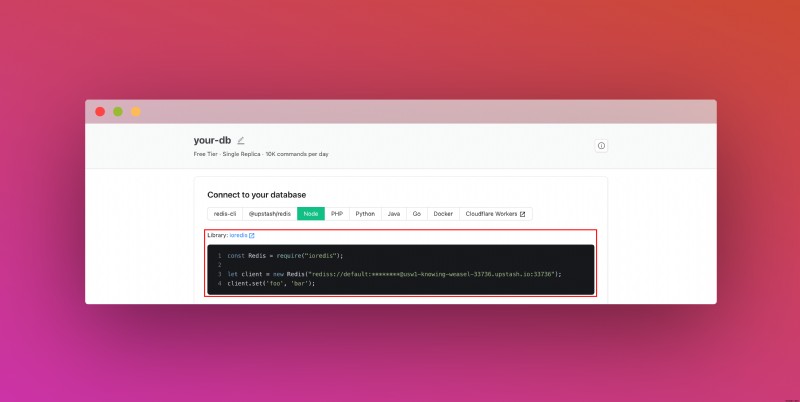
Sau khi tạo xong, vào tab Details. Cuộn xuống Connect your database. Sao chép nội dung lưu an toàn.
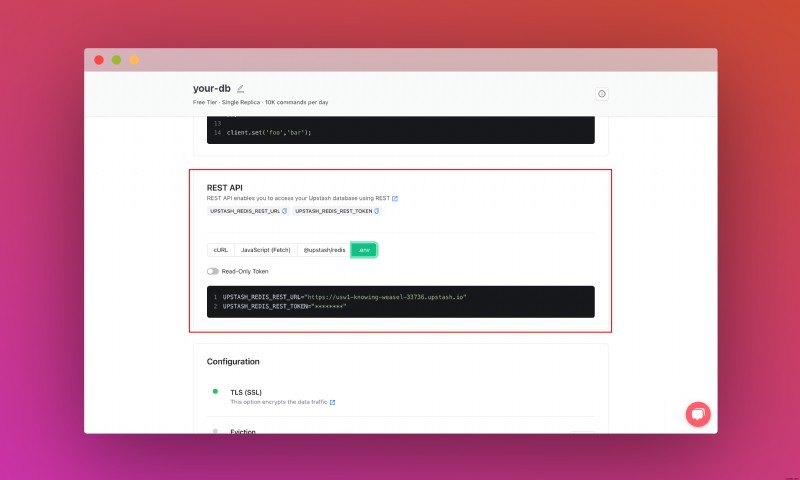
Cuộn xuống phần REST API, chọn nút .env. Sao chép lưu an toàn.
Thiết Lập Upstash QStash
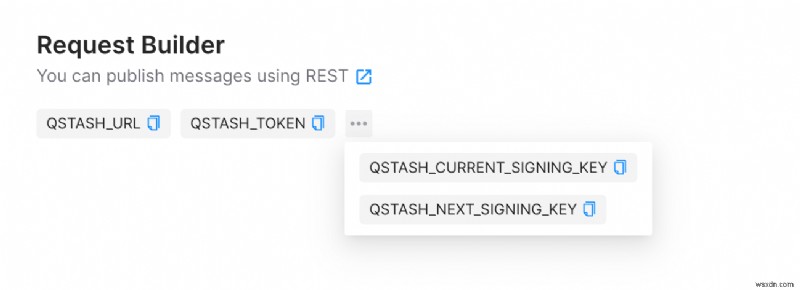
Đăng nhập, vào tab QStash lấy QSTASH_URL, QSTASH_TOKEN, QSTASH_CURRENT_SIGNING_KEY, QSTASH_NEXT_SIGNING_KEY. Sao chép lưu an toàn.
Thiết Lập Dự Án
Clone repo và làm theo tutorial:
git clone https://github.com/rishi-raj-jain/custom-content-ai-chatbot
cd custom-content-ai-chatbot
npm install
Tạo file .env với items từ trên:
# .env
# Upstash Redis Secrets
UPSTASH_REDIS_REST_URL="https://....upstash.io"
UPSTASH_REDIS_REST_TOKEN="..."
# Upstash QStash Secrets
QSTASH_URL="https://qstash.upstash.io/v1/publish/"
QSTASH_TOKEN="..."
QSTASH_CURRENT_SIGNING_KEY="sig_..."
QSTASH_NEXT_SIGNING_KEY="sig_..."
# OpenAI Key
OPENAI_API_KEY="sk-..."
# Admin Access Key
# Dùng verify training request chỉ do admin thực hiện
ADMIN_KEY="..."
Khởi chạy local:
npm run devCấu Trúc Repository
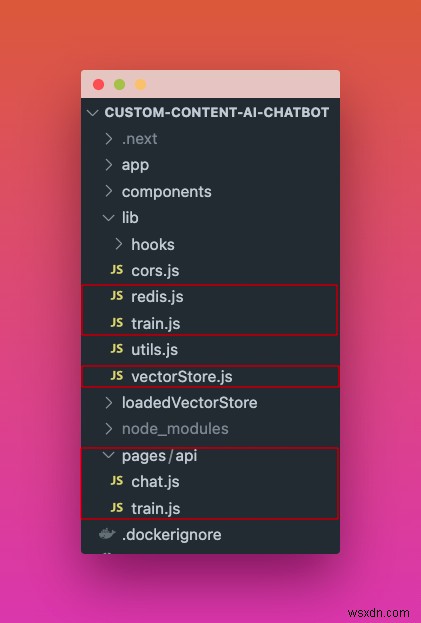
Cấu trúc thư mục chính. File quan trọng (đánh dấu đỏ) thảo luận về: quản lý vector store, tạo API Routes chat với AI trained on custom content (caching responses), và schedule model training process.
High-Level Data Flow Và Operations
Sơ đồ high-level data flow và operations:
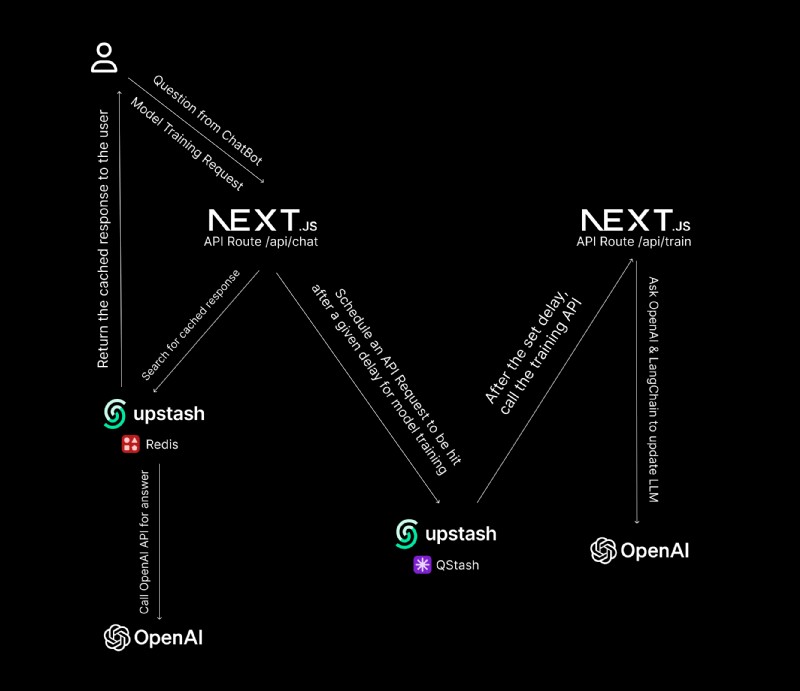
- User hỏi chatbot → IP check rate limit → response (nếu không cached qua Upstash Redis, query OpenAI API rồi cache) → stream về user
- Admin request training model trên set URLs → Upstash QStash tạo POST request serverless sau delay (10s) fetch content URLs và update model (background)
Setup Chat Và Train API Routes Trong Next.js
Route pages/api/chat.js: enable CORS, rate limit chat API calls, cache và stream responses, expose method schedule content training trên URLs. Route pages/api/train.js: chỉ perform training trên URLs nhưng background.
1. Enable CORS
Dùng package cors enable CORS dùng chatbot ở nhiều nơi (bot trên website). Khởi chạy cors setup khi API Route init:
// File: pages/api/chat.js
import { runMiddleware } from '@/lib/cors'
export default async function (req, res) {
  try {
    await runMiddleware(req, res)
    // ...
  } catch (e) { console.log(e.message || e.toString()) }
  return res.end()
}
// Cors Function
// File: lib/cors.js
import Cors from 'cors'
const cors = Cors({ methods: ['POST', 'OPTIONS', 'HEAD'] })
export function runMiddleware(req, res, fn = cors) {
  return new Promise((resolve, reject) => {
    fn(req, res, (result) => {
      if (result instanceof Error) return reject(result)
      return resolve(result)
    })
  })
}
2. Schedule Content Training Request(s) Trên URLs Cho Trước
Với Upstash QStash, tạo API fire-and-forget. Không cần wait main function finish để response, làm background (optionally sau delay). Giống cron-job nhưng chạy per request không phải scheduled intervals.
Trong chat api route, accept request có header admin-key match server secret ADMIN_KEY → schedule content training trên URLs trong request body sau delay (10s). Request training sau delay gọi endpoint https://custom-content-ai-chatbot.fly.dev/api/train.
// File: pages/api/chat.js
if (req.headers['admin-key'] === process.env.ADMIN_KEY) {
  if (!req.body.urls) return res.status(400).send('No urls to train on.')
  await qstashClient.publishJSON({
    delay: 10,
    body: { urls: req.body.urls },
    url: 'https://custom-content-ai-chatbot.fly.dev/api/train'
  })
  return res.status(200).end()
}
Train API route (pages/api/train.js):
// File: pages/api/train.js
import train from '@/lib/train'
import * as dotenv from 'dotenv'
import { redis } from '@/lib/redis'
import { runMiddleware } from '@/lib/cors'
import { verifySignature } from '@upstash/qstash/nextjs'
dotenv.config()

export const config = {
  api: { bodyParser: false },
}

async function handler(req, res) {
  try {
    await runMiddleware(req, res)
    if (req.method !== 'POST') return res.status(403).send('No other methods allowed.')
    if (!req.body.urls) return res.status(400).send('No urls to train on.')
    await train(req.body.urls)
    let allKeys = await redis.keys('*')
    if (allKeys) {
      allKeys = allKeys.filter((i) => !i.includes('@upstash/ratelimit:'))
      const p = redis.pipeline()
      allKeys.forEach((i) => p.del(i))
      await p.exec()
      console.log('Cleaned cached responses in Upstash.')
    }
    return res.status(200).end()
  } catch (e) { console.log(e.message || e.toString()) }
  return res.end()
}
export default verifySignature(handler)
3 critical actions:
- Verify incoming request bằng QStash
verifySignature(checkUpstash-Signatureheader với raw body). - Gọi
trainfunction fetch URL content và add vào vector store (và save). - Clear cached responses Upstash Redis sau filter keys rate limiting via Redis Transactions.
3. Rate Limiting
Implement rate-limiting dùng Upstash Redis client và library @upstash/ratelimit.
// File: lib/redis.js
import * as dotenv from 'dotenv'
import { Redis } from '@upstash/redis'
import { Ratelimit } from '@upstash/ratelimit'
dotenv.config()
export const redis = new Redis({
  url: process.env.UPSTASH_REDIS_REST_URL,
  token: process.env.UPSTASH_REDIS_REST_TOKEN,
})
export const ratelimit = {
  chat: new Ratelimit({
    redis,
    limiter: Ratelimit.slidingWindow(30, '86400s'),
  }),
}
Nhờ Rate Limiting, có thể làm service hoàn toàn free và public! Ai cũng có thể hỏi 30 câu/ngày via website. Enforce rate limit 30 questions/ngày dựa trên IP address làm key.
// File: pages/api/chat.js
import requestIp from 'request-ip'
import { ratelimit } from '@/lib/redis'
// ...
const detectedIp = requestIp.getClientIp(req)
if (!detectedIp) return res.status(400).send('Bad request.')
const result = await ratelimit.chat.limit(detectedIp)
if (!result.success) return res.status(400).send('Rate limit exceeded.')
// Continue serving chat responses
4. Load Saved Indexed Vector Store Và Hỏi OpenAI Responses
Sau checks, tiến hành main work — call OpenAI API với custom content, send response user.
4.1: Retrieving Saved Vector Store
// File: pages/api/chat.js
import { loadVectorStore } from '@/lib/vectorStore'
const vectorStore = await loadVectorStore()
// ...
// Vector Store Function
// File: lib/vectorStore.js
import { join } from 'path'
import { existsSync } from 'fs'
import { Document } from 'langchain/document'
import { FaissStore } from 'langchain/vectorstores/faiss'
import { OpenAIEmbeddings } from 'langchain/embeddings/openai'
export async function loadVectorStore() {
  const directory = join(process.cwd(), 'loadedVectorStore')
  const docStoreJSON = join(process.cwd(), 'loadedVectorStore', 'docstore.json')
  if (existsSync(docStoreJSON)) {
    return await FaissStore.load(directory, new OpenAIEmbeddings())
  } else {
    return await FaissStore.fromDocuments([new Document({ pageContent: 'Hey' })], new OpenAIEmbeddings())
  }
}
4.2: Thêm Prompt Guidelines Cho User Queries
Dùng PromptTemplate LangChain, với user query pass instructions cách AI trả lời:
// File: pages/api/chat.js
import { z } from 'zod'
import { PromptTemplate } from 'langchain/prompts'
import { RetrievalQAChain } from 'langchain/chains'
import { OutputFixingParser, StructuredOutputParser } from 'langchain/output_parsers'
// ...
const outputParser = StructuredOutputParser.fromZodSchema(
  z.object({
    answer: z.string().describe('answer to question in HTML friendly format, use all tags wherever possible and including reference links'),
  }),
)
const outputFixingParser = OutputFixingParser.fromLLM(model, outputParser)
const prompt = new PromptTemplate({
  template: `Answer the user's question as best and be as detailed as possible:\n{format_instructions}\n{query}`,
  inputVariables: ['query'],
  partialVariables: { format_instructions: outputFixingParser.getFormatInstructions() },
})
const chain = RetrievalQAChain.fromLLM(model, vectorStore.asRetriever(), prompt)
4.3: Stream Và Cache Responses
Cache responses Upstash Redis dùng UpstashRedisCache cache library LangChain. Pass existing Redis instance as client, pass caching handler cho ChatOpenAI wrapper dùng cache khi deliver responses:
// File: pages/api/chat.js
import { redis } from '@/lib/redis'
import { ChatOpenAI } from 'langchain/chat_models/openai'
import { UpstashRedisCache } from 'langchain/cache/upstash_redis'
// ...
const upstashRedisCache = new UpstashRedisCache({ client: redis })
let doesToken = false
const model = new ChatOpenAI({
  streaming: true,
  cache: upstashRedisCache,
  callbacks: [{
    handleLLMNewToken(token) {
      doesToken = true
      res.write(token)
    },
  }],
})
// ...
const chainOutput = await chain.call({ query: req.body.input })
if (!doesToken) return res.status(200).send(chainOutput.text)
Triển Khai Lên Fly.io
Repo có baked-in setup Fly.io:
- Dockerfile
- fly.toml
- .dockerignore
Deploy cần account Fly.io. Tạo app Fly.io chạy command tại root folder:
fly launchDeploy:
fly deployXong deployment! Đó là tất cả.
Kết Luận
Tóm lại, dự án cung cấp kinh nghiệm quý giá implement OpenAI response caching, rate limiting, scheduled API requests train model, all dùng service scale theo nhu cầu — Upstash.
Next.js, Redis, TailwindCSS, LangChain, Serverless Scheduling