
Giới Thiệu
Trong bài viết này, tôi chia sẻ cách xây dựng một Custom Content RAG Chatbot open-source sử dụng Upstash Vector, Upstash Redis, Hugging Face Inference API, Replicate LLAMA-2-70B Chat model và Vercel. Upstash Vector giúp chèn và truy vấn vector, tạo/cập nhật context liên quan động cho mỗi tin nhắn người dùng, còn Upstash Redis lưu trữ lịch sử hội thoại chatbot.
Yêu Cầu Tiên Quyết
- Node.js 18 trở lên
- Tài khoản Upstash
- Tài khoản Hugging Face
- Tài khoản Replicate
- Tài khoản Vercel
Công Nghệ Sử Dụng
| Công Nghệ | Mô Tả |
|---|---|
| Upstash | Nền tảng DB serverless. Sử dụng Upstash Vector và Upstash Redis để lưu vector và hội thoại tương ứng. |
| Next.js | React Framework cho Web. Dùng shadcn/ui cho prototyping nhanh. |
| Replicate | Chạy và fine-tune model open-source. Sử dụng LLAMA-2-70B Chat model. |
| Hugging Face | Nền tảng cộng đồng ML cộng tác model, dataset, app. Dùng Hugging Face Inference API tạo embedding. |
| LangChain | Framework phát triển ứng dụng dựa trên language model. |
| TailwindCSS | Framework CSS thiết kế tùy chỉnh. |
| Vercel | Nền tảng đám mây triển khai và mở rộng web app. |
Thiết Lập Upstash Redis
Đăng nhập Upstash, vào tab Redis và tạo database.
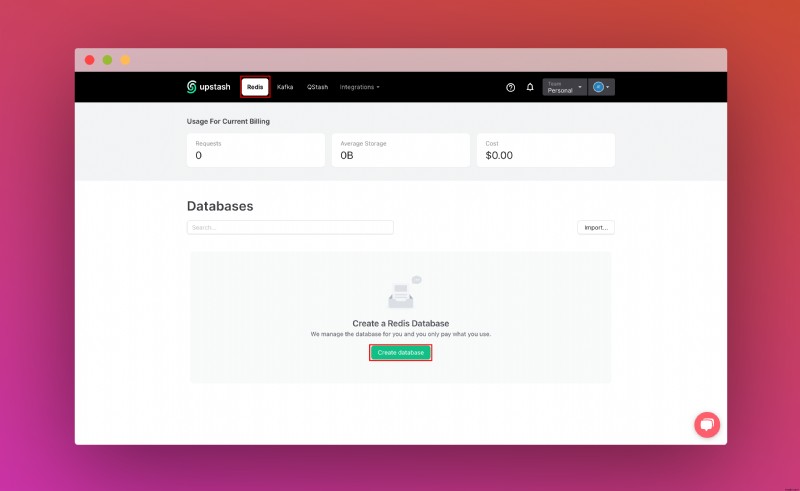
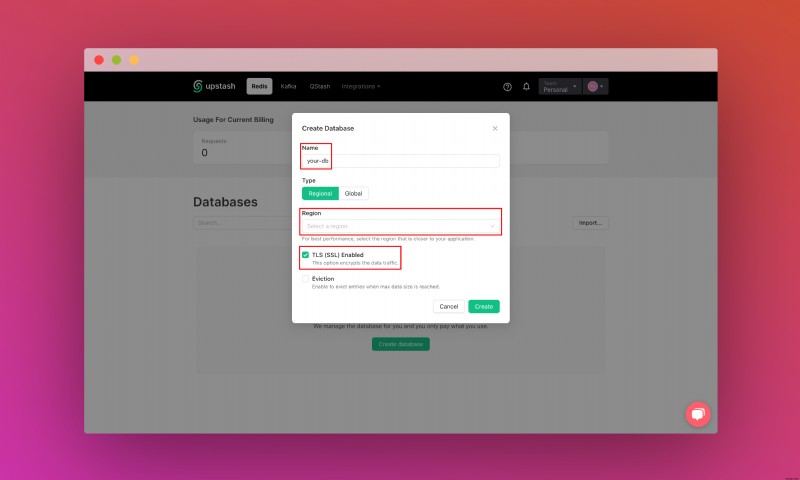
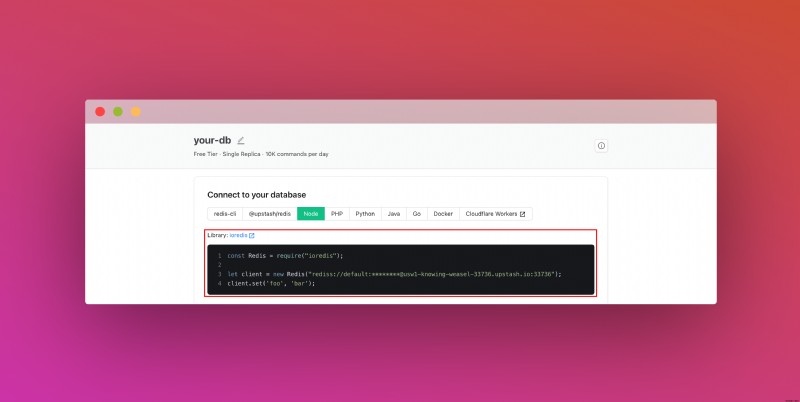
Sau khi tạo xong, vào tab Details. Cuộn xuống phần Connect your database. Sao chép nội dung và lưu an toàn.
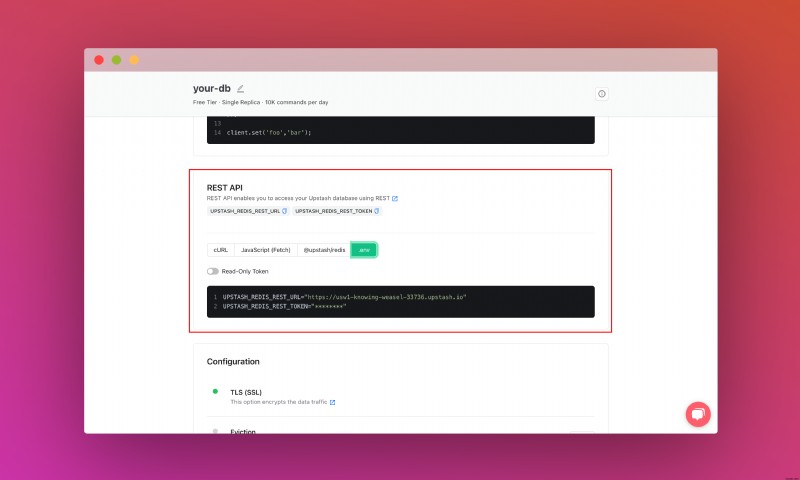
Cuộn tiếp đến phần REST API, chọn nút .env. Sao chép và lưu an toàn.
Thiết Lập Upstash Vector
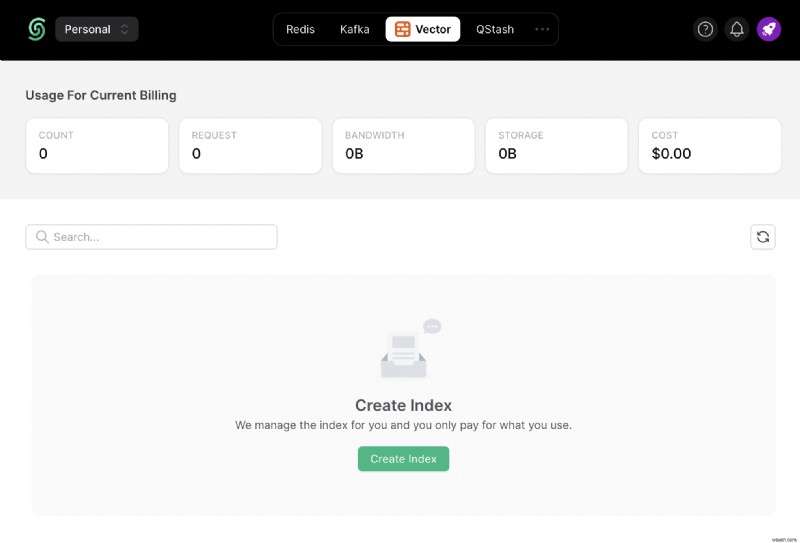
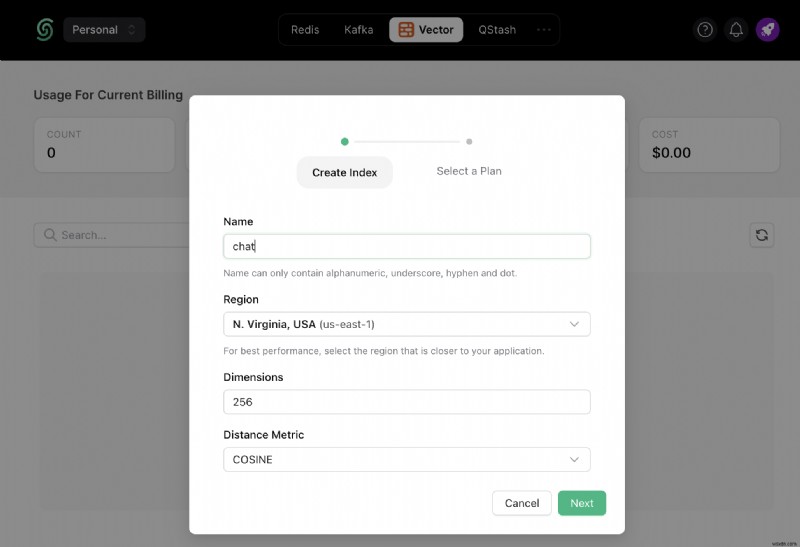
Vào tab Vector và tạo Index.
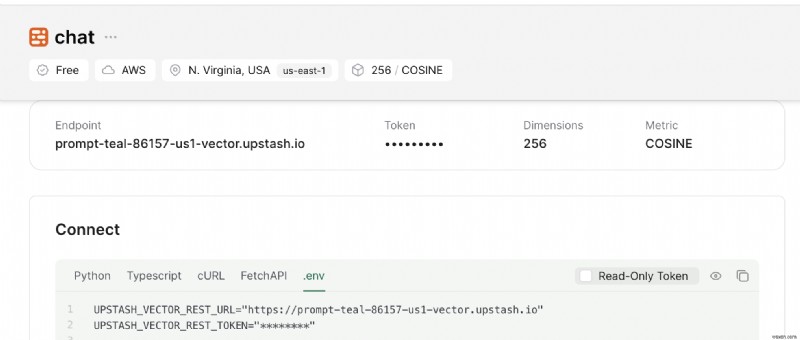
Cuộn xuống phần Connect, chọn nút .env. Sao chép và lưu an toàn.
Thiết Lập Dự Án
Clone repo và làm theo tutorial:
git clone https://github.com/rishi-raj-jain/custom-rag-chatbot-upstash-vector
cd custom-rag-chatbot-upstash-vector
pnpm install
Tạo file .env với các biến từ các bước trên:
# .env
# Upstash Redis URL and Token
UPSTASH_REDIS_REST_URL="https://....upstash.io"
UPSTASH_REDIS_REST_TOKEN="..."
# Upstash Vector URL and Token
UPSTASH_VECTOR_REST_URL="https://...-vector.upstash.io"
UPSTASH_VECTOR_REST_TOKEN="..."
# Replicate API Key
REPLICATE_API_TOKEN="r8_..."
# Hugging Face Inference API Key
HUGGINGFACEHUB_API_KEY="hf_..."
Khởi chạy local:
pnpm devCấu Trúc Repository
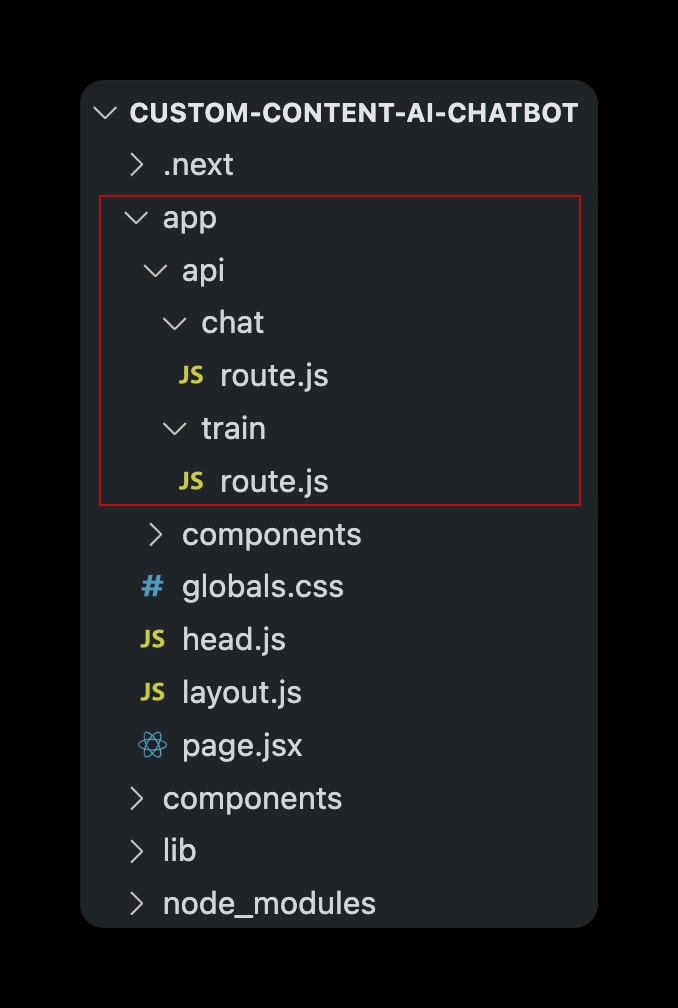
Cấu trúc thư mục chính. Các file quan trọng (đánh dấu đỏ) sẽ được thảo luận chi tiết về API Routes chat với AI trained on custom context, và cập nhật context bằng cách upsert vector vào index.
Thiết Lập Chat Route Trong Next.js App Router
Route app/api/chat/route.js đồng bộ hội thoại trong serverless DB, tạo embedding động của chuỗi, truy vấn vector liên quan từ index để tạo context, và yêu cầu dự đoán từ LLAMA-2-70B Chat model.
Lưu Trữ Hội Thoại
Dùng Redis Lists để cache hội thoại. Khi có tin nhắn từ user, có điều kiện push response trước đó của chatbot vào list, rồi lưu tin nhắn mới nhất của user vào list, sau đó tiến hành phản hồi.
// File: app/api/chat/route.js
import { Redis } from '@upstash/redis'

const upstashRedis = new Redis({
  url: process.env.UPSTASH_REDIS_REST_URL,
  token: process.env.UPSTASH_REDIS_REST_TOKEN,
})

export async function POST(req) {
  try {
    const { messages } = await req.json()
    if (messages.length > 1) {
      await upstashRedis.lpush('unique_conversation_id', JSON.stringify(messages[messages.length - 2]))
    }
    await upstashRedis.lpush('unique_conversation_id', JSON.stringify(messages[messages.length - 1]))
    // Tiếp tục tạo phản hồi
  }
}
Tạo Embedding Của Tin Nhắn Mới Nhất
Để trả lời hiệu quả trong mọi context (nội dung tùy chỉnh user cung cấp), tạo embedding để retrieve context liên quan (vector tương tự) từ index hiện có. Dùng Hugging Face Inference API với LangChain tạo embedding qua một API call trên edge, slice vector đến độ dài cấu hình khi tạo Upstash Vector Index (ở đây 256).
// File: app/api/chat/route.js
import { HuggingFaceInferenceEmbeddings } from '@langchain/community/embeddings/hf'

const embeddings = new HuggingFaceInferenceEmbeddings()

export async function POST(req) {
  try {
    // ...
    const userMessages = messages.filter((i) => i.role === 'user')
    const lastMessage = userMessages[userMessages.length - 1].content
    const queryVector = (await embeddings.embedQuery(lastMessage)).slice(0, 256)
    // Tiếp tục tạo phản hồi
  }
}
Truy Xuất Context Vector Liên Quan Dựa Trên Tin Nhắn Mới Nhất
Fetch toàn bộ context user cung cấp cho mỗi tin nhắn là tốn kém. Chỉ dùng context liên quan đến tin nhắn mới nhất, truyền cho LLAMA-2-70B Chat model làm system prompt. Query tập vector hiện có để lấy 2 vector liên quan nhất kèm metadata, lọc kết quả confidence score > 70%.
// File: app/api/chat/route.js
import { Index } from '@upstash/vector'

const upstashVectorIndex = new Index()

export async function POST(req) {
  try {
    // ...
    const queryResult = await upstashVectorIndex.query({
      vector: queryVector,
      topK: 2,
      includeVectors: false,
      includeMetadata: true,
    })

    const queryPrompt = queryResult
      .filter((match) => match.score && match.score > 0.7)
      .map((match) => match.metadata.description)
      .join('\n')
    // Tiếp tục tạo phản hồi
  }
}
Prompt LLAMA-2-70B Chat Model Với Context Để Dự Đoán
Sau khi có context liên quan dạng string, bước cuối là prompt llama-2-70b chat model cho tin nhắn mới nhất. Dùng experimental_buildLlama2Prompt từ Vercel AI SDK để tạo format prompt phù hợp cho llama-2-70b chat model.
// File: app/api/chat/route.js
import Replicate from 'replicate'
import { experimental_buildLlama2Prompt } from 'ai/prompts'
import { ReplicateStream, StreamingTextResponse } from 'ai'

const replicate = new Replicate({ auth: process.env.REPLICATE_API_TOKEN })

export async function POST(req) {
  try {
    // ...
    const response = await replicate.predictions.create({
      stream: true,
      version: '2c1608e18606fad2812020dc541930f2d0495ce32eee50074220b87300bc16e1',
      input: {
        prompt: experimental_buildLlama2Prompt([
          {
            role: 'system',
            content: queryPrompt.substring(0, Math.min(queryPrompt.length, 2000)),
          },
          ...messages,
        ]),
      },
    })
    const stream = await ReplicateStream(response)
    return new StreamingTextResponse(stream)
  }
}
Thiết Lập Train Route Trong Next.js App Router
Route app/api/train/route.js tạo embedding động của chuỗi từ request object và thêm vào Upstash Vector Index.
Tạo Embeddings Của Các Chuỗi
Tạo embeddings để set/cập nhật index hiện có, giữ context cho phản hồi chatbot tương lai luôn cập nhật. Dùng Hugging Face Inference API với LangChain tạo embedding qua API call trên edge.
// File: app/api/train/route.js
import { HuggingFaceInferenceEmbeddings } from '@langchain/community/embeddings/hf'

const embeddings = new HuggingFaceInferenceEmbeddings()

export async function POST(req) {
  try {
    let messagesToVectorize = [
      'Rishi is pretty much active on Twitter nowadays.',
      'Rishi loves writing for Upstash',
      "Rishi's recent article on building chatbot using Upstash went viral",
      'Rishi is enjoying building launchfa.st.',
    ]

    if (req.headers.get('Content-Type') === 'application/json') {
      const { messages } = await req.json()
      if (typeof messages !== 'string' && messages.length > 0) {
        messagesToVectorize = messages
      }
    }

    const generatedEmbeddings = await Promise.all(messagesToVectorize.map((i) => embeddings.embedQuery(i)))
    // ...
  }
}
Lưu Vector Cho Tìm Kiếm Liên Quan
Thêm embedding đã tạo vào vector index: slice vector đến độ dài cấu hình (256) và dùng upsert để chèn embedding kèm metadata (chính các chuỗi đó). Điều này cho phép retrieve chuỗi khi search vector tương tự, từ đó set knowledge base cho hội thoại khi gọi LLAMA-2-70B Chat model.
// File: app/api/train/route.js
import { Index } from '@upstash/vector'

const upstashVectorIndex = new Index()

export async function POST(req) {
  try {
    // ...
    await Promise.all(
      generatedEmbeddings
        .map((i) => i.slice(0, 256))
        .map((vector, index) =>
          upstashVectorIndex.upsert({
            vector,
            id: index.toString(),
            metadata: { description: messagesToVectorize[index] },
          }),
        ),
    )
    return new Response(JSON.stringify({ code: 1 }), {
      status: 200,
      headers: { 'Content-Type': 'application/json' },
    })
  }
}
Triển Khai Lên Vercel
- Tạo GitHub repository chứa code app.
- Vào Vercel Dashboard, tạo New Project.
- Liên kết với GitHub repository.
- Trong Settings, cập nhật
Environment Variableskhớp với.envlocal. - Deploy! 🚀
Thông Tin Thêm
Tham khảo các tài liệu trích dẫn trong bài viết.
Kết Luận
Tóm lại, dự án này cung cấp kinh nghiệm quý giá trong việc tạo embeddings, query từ tập vector hiện có, và dùng context để tạo dự đoán liên quan với LLAMA-2-70B Chat model, đồng thời sử dụng dịch vụ scale theo nhu cầu — Upstash.