
Chúng Ta Đang Xây Gì
Trong bài này, chúng ta xây dựng LLM stream cực kỳ durable dễ dàng survive:
- Network outage
- Page refresh
- Đóng website
- Đóng nắp laptop
Bonus: Bạn có thể xem cùng stream trên nhiều device (ví dụ phone và laptop) cùng lúc.
Không matter bạn cố gắng break stream như thế nào, nó tiếp tục background khi bạn disconnect và smoothly continue khi bạn quay lại. Đây là trải nghiệm user tuyệt vời.
Durable LLM streams demo 👇
Cảm Hứng
Khi build với AI, best practice là stream AI response real-time.
Thay vì đợi whole response, user thấy content real-time khi nó được generate — amazing cho UX. Tool như AI SDK by Vercel làm điều này cực dễ:
import { openai } from "@ai-sdk/openai"; import { streamText } from "ai"; const { textStream } = streamText({ model: openai("gpt-4o"), prompt: "Invent a new holiday and describe its traditions.", });Để làm real-time LLM stream work technical level, bạn connect client đến API và stream data back dùng protocol như Server Sent Events (SSE):
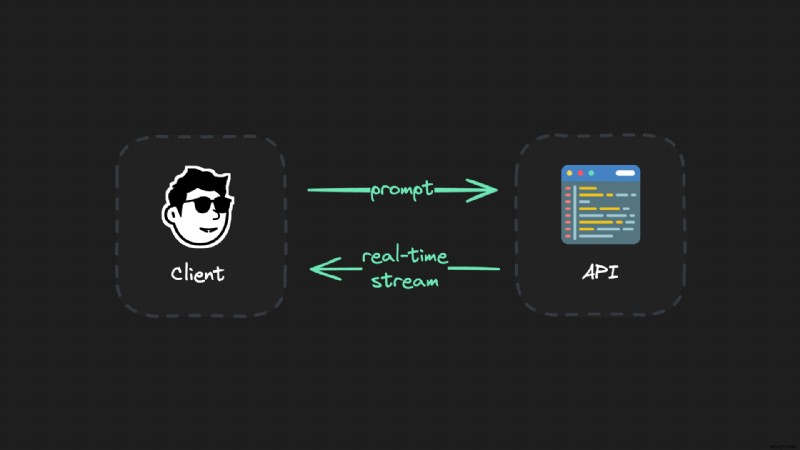
Nhưng: setup này có vấn đề.
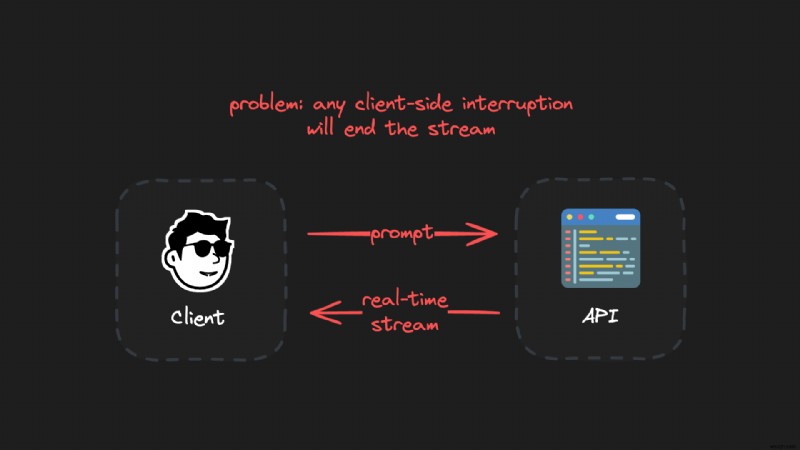
Nếu bất cứ điều gì xảy ra trong stream, như internet disconnect, đóng nắp laptop, hoặc network hiccup, toàn bộ generation mất. Bạn cần bắt đầu lại và đợi entire generation again. Điều này đặc biệt annoying cho generation dài (ví dụ model đắt như O1).
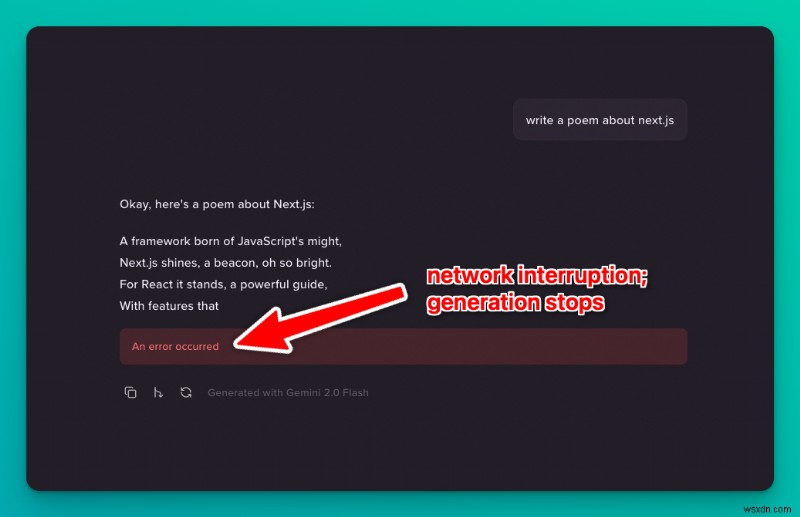
Rõ ràng vấn đề này trên radar mọi người. Có real demand cho reliable real-time LLM streaming, và nhiều dev đang experiment cách làm nó work:
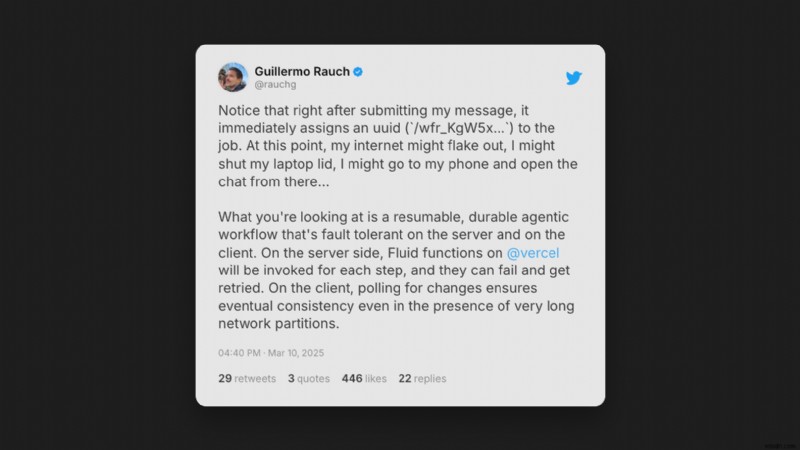
Xây Dựng High-Durability LLM Streams
Bí mật cho truly durable, resumable LLM streams là tách client khỏi generation environment. Client connection unstable và có thể disconnect vì nhiều lý do, như đóng laptop, network problem, hoặc refresh page.
Bằng cách giữ client và generation process riêng biệt, generation luôn tiếp tục uninterrupted. Client có thể reconnect bất kỳ lúc nào — không interrupt generation đang chạy.
Bad idea: Persistent, direct connection:
Good idea: Replaceable, interruptible stream connection:
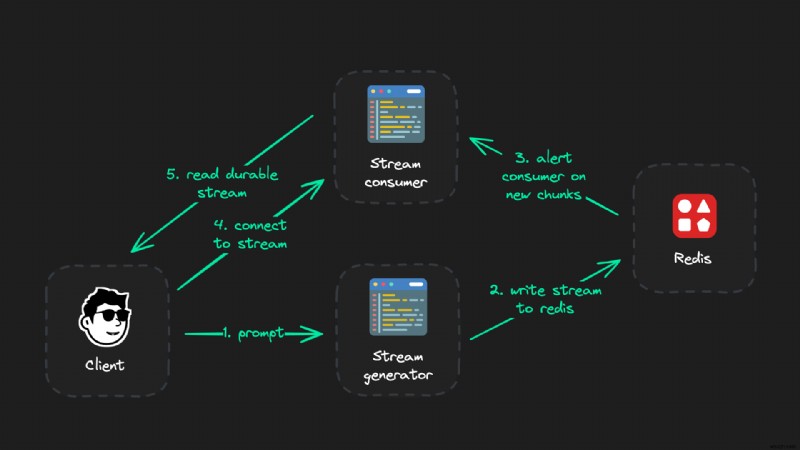
Và đúng — kiến trúc này có vẻ khá complex cho simple AI stream. Như bạn sẽ thấy trong code ngay bây giờ, này chỉ vài dòng code và mất vài phút implement.
Setup Durable Streams
Extremely reliable LLM stream setup có ba phần:
- The client (frontend)
- The stream generator (một API route)
- The stream consumer (cũng một API route)
Tất cả connection trực tiếp đến client có thể interrupt hoặc pause bất kỳ lúc nào. Logic piece chịu trách nhiệm generate LLM output stream (stream generator) nên là independent API không bao giờ có active connection đến client.
Thay vào đó, chúng ta connect đến client qua consumer — chỉ đọc data từ Redis và ngoài ra khá "ngu". Mục đích duy nhất: đọc output của generator và push tất cả LLM chunk client chưa thấy khi client connect. Đó là nó.
Quick summary - mỗi phần làm gì:
- Client: Trigger stream generator (nhưng không maintain open connection) và render real-time stream
- Stream generator: Generate LLM output real-time và publish vào Redis
- Stream consumer: Đọc stream của generator và push chunk đến client
Generator chỉ chịu trách nhiệm đọc LLM stream và publish vào Redis real-time. Chúng ta có replaceable connection từ client đến stream consumer có thể end, reconnect, v.v. — không gì affect stream generator.
Code Examples
Trong section này, xem code. Để làm rõ principle, xem actual, complete production code implementation ở cuối.
Hiện tại, dễ hiểu code hơn nếu xem core snippets và purpose thay vì entire code files.
1. The Client
Client chỉ có 3 trách nhiệm:
- Generate session IDs
- Trigger generator
- Render generation stream
Hãy xem từng thứ:
Client: Generating Session IDs
Khi client connect hoặc reconnect đến stream, chúng ta muốn gửi tất cả message client chưa thấy. Nghĩa là trong active stream, mỗi message chỉ chứa exact delta client cần thấy, không phải entire stream.
Khi reconnect, entire stream đến current generation point được gửi và subscription đến tất cả future event seamless không missing chunk.
How?
Redis Streams, cách efficient store và retrieve real-time data, có not-yet-seen functionality built-in qua consumer groups. Chỉ cần: đảm bảo mỗi client có unique session — nghĩa là assign mỗi generation unique ID.
Chúng ta sẽ học thêm consumer groups khi xem stream consumer. Chúng trông như:
await redis.xgroup("redis-key", { type: "CREATE", group: "my-group-name", id: "0", });Toàn bộ logic client nào đã thấy stream nào đến đâu và piece nào missing hoàn toàn được handle bởi Redis streams với guaranteed precision. Chúng ta không bao giờ missing LLM chunk và luôn gửi exactly data client cần.
Chỉ điều client cần làm: assign ID cho mỗi generation. Chúng ta đơn giản dùng nanoid:
import { customAlphabet } from "nanoid" const nanoid = customAlphabet("0123456789", 6);Client: Triggering a Generation Stream
Interaction duy nhất client có với generation engine là trigger nó. Technical nói, bạn có thể trigger generation từ đâu đó khác (ví dụ CRON jobs, automated pipelines).
Dưới dạng đơn giản, chỉ là fetch call đến generation API route:
// 👇 trigger stream generator await fetch("/api/llm-stream", { method: "POST", headers: { "Content-Type": "application/json", }, body: JSON.stringify({ prompt, sessionId }), });Client: Reading a Generation Stream
Sau khi trigger generation, generator bắt đầu stream LLM output vào centralized Redis store — hoàn toàn decoupled từ client. Hãy connect đến stream consumer đọc generation stream:
// 👇 connect to stream consumer const res = await fetch(`/api/check-stream?sessionId=${sessionId}`, { headers: { "Content-Type": "text/event-stream" }, });Xong!
Đó là ba trách nhiệm của client. Tất nhiên, chúng ta có thể fancy hơn với custom hook cho ID generation, react-query cho reliability thêm — chúng ta sẽ đến đó trong complete code examples sau.
2. The Stream Generator
Stream generator mở LLM stream và write mỗi chunk vào Redis stream. Nó publish message cho mỗi chunk written để alert stream consumer về new data cho real-time update.
Note: Lại, này intentionally không phải full code example. Chúng ta sẽ đến full code ở cuối — này để hiểu concept.
import { streamText } from "ai" import { redis } from "@/utils" const result = await new Promise( async (resolve, reject) => { const { textStream } = streamText({ model: openai("gpt-4o"), prompt, onError: (err) => reject(err), onFinish: async () => { resolve({ // ... }), }) for await (const chunk of textStream) { if (chunk) { const chunkMessage: ChunkMessage = { type: MessageType.CHUNK, content: chunk, } // 👇 write chunk to redis stream await redis.xadd(streamKey, "*", chunkMessage) // 👇 alert consumer that there's a new chunk await redis.publish(streamKey, { type: MessageType.CHUNK }) } } } )3. The Stream Consumer
Stream consumer connect đến Redis và listen new chunk alert qua Redis pub/sub. Mỗi client có consumer group riêng track seen/unseen message.
Note: Publish không transfer actual chunk, chỉ alert new chunk available trong stream.
Khi new chunk available, stream consumer API đọc từ stream và forward đến tất cả connected client. Redis consumer group track client nào đã thấy gì để guarantee transfer no duplicate hoặc missing chunk.
Core stream consumer trông như:
const streamKey = `llm:stream:${sessionId}`; const groupName = `sse-group-${nanoid()}`; await redis.xgroup(streamKey, { type: "CREATE", group: groupName, id: "0", }); const readStreamMessages = async () => { const chunks = (await redis.xreadgroup( groupName, `consumer-1`, streamKey, // 👇 built-in Redis stream functionality: only send unseen messages ">" )) as StreamData[]; if (chunks?.length > 0) { const [_streamKey, messages] = chunks[0]; for (const [_messageId, fields] of messages) { const rawObj = arrToObj(fields); const validatedMessage = validateMessage(rawObj); if (validatedMessage) { controller.enqueue(json(validatedMessage)); } } } }; // 👇 initial read await readStreamMessages(); const subscription = redis.subscribe(streamKey); subscription.on("message", async () => { // 👇 read every time a new chunk is written to stream await readStreamMessages(); });Note: Chúng ta tạo consumer group mỗi connection. Điều này work tốt vì Redis handle operation idempotently, ví dụ nothing happens nếu group đã tồn tại.
Full Code
SessionID Generation
Cho đến nay, xem individual pieces để hiểu client task, stream generator, stream consumer individually. Bây giờ, xem cách pieces fit together bằng full implementation.
Để bắt đầu, tạo sessionId nên resilient hơn chỉ dùng nanoid().畢竟, nếu website refresh hoặc close? Upon reconnect, chúng ta mất generated sessionId nếu không store ở đâu — nó cần persist طوال generation run.
May mắn localStorage perfect cho này:
import { customAlphabet } from "nanoid"; import { useRouter } from "next/navigation"; import { useCallback, useEffect, useState } from "react"; export const useLLMSession = () => { const [sessionId, setSessionId] = useState<string>(""); const router = useRouter(); const nanoid = customAlphabet("0123456789", 6); const updateUrlWithSessionId = useCallback( (id: string) => { const url = new URL(window.location.href); url.searchParams.set("sessionId", id); router.replace(url.toString(), { scroll: false }); }, [router], ); useEffect(() => { const urlParams = new URLSearchParams(window.location.search); const urlSessionId = urlParams.get("sessionId"); const storedSessionId = localStorage.getItem("llm-session-id"); if (urlSessionId) { localStorage.setItem("llm-session-id", urlSessionId); setSessionId(urlSessionId); } else if (storedSessionId) { setSessionId(storedSessionId); updateUrlWithSessionId(storedSessionId); } else { const newSessionId = nanoid(); localStorage.setItem("llm-session-id", newSessionId); setSessionId(newSessionId); updateUrlWithSessionId(newSessionId); } // eslint-disable-next-line react-hooks/exhaustive-deps }, []); const clearSessionId = useCallback(() => { localStorage.removeItem("llm-session-id"); setSessionId(""); const url = new URL(window.location.href); url.searchParams.delete("sessionId"); router.replace(url.toString(), { scroll: false }); }, [router]); const regenerateSessionId = () => { const newSessionId = nanoid(); localStorage.setItem("llm-session-id", newSessionId); setSessionId(newSessionId); updateUrlWithSessionId(newSessionId); return newSessionId; }; return { sessionId, regenerateSessionId, clearSessionId, }; };Client
Chúng ta đã thấy hai phần quan trọng nhất của client: start stream và connect stream. Khi có confirmation từ API generator running, connect stream dùng react-queries refetch utility invoke connection query.
Đây là cách tất cả pieces fit together:
app/page.tsx"use client" import { useLLMSession } from "@/use-llm-session" import { useMutation, useQuery } from "@tanstack/react-query" import { FormEvent, useRef, useState, useEffect } from "react" import { MessageType, validateMessage, type ChunkMessage, type MetadataMessage, StreamStatus, } from "@/lib/message-schema" // precondition = stream is ready to read class PreconditionFailedError extends Error { constructor(message: string) { super(message) this.name = "PreconditionFailedError" } } export default function Home() { const { sessionId, regenerateSessionId, clearSessionId } = useLLMSession() const [prompt, setPrompt] = useState("") const [status, setStatus] = useState< "idle" | "loading" | "streaming" | "completed" | "error" >("idle") const [response, setResponse] = useState("") const [chunkCount, setChunkCount] = useState(0) const controller = useRef<AbortController | null>(null) const responseRef = useRef<HTMLDivElement>(null) const isInitialRequest = useRef(true) // keep generation in viewport useEffect(() => { if (responseRef.current) { responseRef.current.scrollTop = responseRef.current.scrollHeight } }, [response]) // start generator const { mutate, error, isIdle } = useMutation({ mutationFn: async (newSessionId: string) => { controller.current?.abort() isInitialRequest.current = false await fetch("/api/llm-stream", { method: "POST", headers: { "Content-Type": "application/json", }, body: JSON.stringify({ prompt, sessionId: newSessionId }), }) }, onSuccess: () => { setStatus("streaming") refetch() }, }) // connect to running stream const { refetch } = useQuery({ queryKey: ["stream", sessionId], queryFn: async () => { if (!sessionId) return null setResponse("") setChunkCount(0) const abortController = new AbortController() controller.current = abortController const res = await fetch(`/api/check-stream?sessionId=${sessionId}`, { headers: { "Content-Type": "text/event-stream" }, signal: controller.current.signal, }) if (res.status === 412) { // stream is not yet ready, retry connection throw new PreconditionFailedError("Stream not ready yet") } if (!res.body) return null const reader = res.body.pipeThrough(new TextDecoderStream()).getReader() let streamContent = "" while (true) { const { value, done } = await reader.read() if (done) break if (value) { const messages = value.split("\n\n").filter(Boolean) for (const message of messages) { if (message.startsWith("data: ")) { const data = message.slice(6) try { const parsedData = JSON.parse(data) const validatedMessage = validateMessage(parsedData) if (!validatedMessage) continue switch (validatedMessage.type) { case MessageType.CHUNK: const chunkMessage = validatedMessage as ChunkMessage streamContent += chunkMessage.content setResponse((prev) => prev + chunkMessage.content) setChunkCount((prev) => prev + 1) break case MessageType.METADATA: const metadataMessage = validatedMessage as MetadataMessage if (metadataMessage.status === StreamStatus.COMPLETED) { setStatus("completed") } break case MessageType.ERROR: setStatus("error") break } } catch (e) { console.error("Failed to parse message:", e) } } } } } return streamContent }, refetchOnWindowFocus: false, refetchOnMount: false, retry(failureCount, error) { if (isInitialRequest.current === true) return false if (error instanceof PreconditionFailedError) { return failureCount < 10 } return false }, }) const handleSubmit = async (e: FormEvent) => { e.preventDefault() setStatus("loading") const newSessionId = regenerateSessionId() mutate(newSessionId) } const handleReset = () => { controller.current?.abort() clearSessionId() setPrompt("") setResponse("") setChunkCount(0) setStatus("idle") } return ( <main className="flex min-h-screen flex-col items-center justify-between p-12 sm:p-24"> <div className="z-10 max-w-5xl w-full items-center justify-between font-mono text-sm"> <h1 className="text-4xl tracking-tight font-bold mb-8 text-center"> Resumable LLM Stream </h1> <form onSubmit={handleSubmit} className="mb-8"> <div className="mb-4"> <label htmlFor="prompt" className="block text-sm font-medium mb-2"> Enter your prompt: </label> <textarea autoFocus id="prompt" value={prompt} onChange={(e) => setPrompt(e.target.value)} className="w-full p-2 border border-zinc-700 rounded-md min-h-[100px] focus:outline-none focus:ring-2 focus:ring-blue-500 focus:border-transparent transition-all duration-200" placeholder="Ask the AI something..." disabled={status === "loading" || status === "streaming"} /> </div> <div className="flex gap-4"> <button type="submit" disabled={status === "loading" || status === "streaming"} className="px-4 py-2 bg-blue-600 text-white rounded-md hover:bg-blue-700 disabled:bg-gray-400" > {status === "loading" ? "Starting..." : status === "streaming" ? "Streaming..." : "Generate Response"} </button> <button type="button" onClick={handleReset} className="px-4 py-2 bg-zinc-600 text-white rounded-md hover:bg-zinc-700" > Reset </button> </div> </form> <div className="mt-8"> <h2 className="text-xl tracking-tight font-semibold mb-2"> Response: </h2> {status === "error" ? ( <div className="p-4 bg-red-100 border border-red-300 rounded-md text-red-800"> <p className="font-bold">Error:</p> <p>{error?.message}</p> </div> ) : status === "idle" && !response ? ( <p className="text-gray-500"> Enter a prompt and click "Generate Response" to see the AI's response. </p> ) : ( <div ref={responseRef} className="flex flex-col h-96 overflow-y-auto p-4 bg-zinc-900 text-zinc-200 border border-zinc-800 rounded-md whitespace-pre-wrap [&::-webkit-scrollbar]:w-2 [&::-webkit-scrollbar-thumb]:bg-zinc-700 [&::-webkit-scrollbar-track]:bg-zinc-800" > <div>{response || "Loading..."}</div> </div> )} {(status === "streaming" || status === "completed") && ( <div className="mt-2 text-sm text-gray-500"> <p>Session ID: {sessionId}</p> <p>Status: {status}</p> <p>Chunks received: {chunkCount}</p> <p> Connection: {status === "streaming" ? "Active SSE" : "Closed"} </p> </div> )} </div> </div> </main> ) }Stream Generator
Đây là toàn bộ code cho stream generator. Nếu LLM generation fail bất kỳ lúc nào, nó tự động retry dùng Upstash Workflow cho maximum reliability:
api/llm-stream/route.tsimport { MessageType, StreamStatus, type ChunkMessage, type MetadataMessage, } from "@/lib/message-schema"; import { redis } from "@/utils"; import { openai } from "@ai-sdk/openai"; import { serve } from "@upstash/workflow/nextjs"; import { streamText } from "ai"; interface LLMStreamResponse { success: boolean; sessionId: string; totalChunks: number; fullContent: string; } export const { POST } = serve(async (context) => { const { prompt, sessionId } = context.requestPayload as { prompt?: string; sessionId?: string; }; if (!prompt || !sessionId) { throw new Error("Prompt and sessionId are required"); } const streamKey = `llm:stream:${sessionId}`; await context.run("mark-stream-start", async () => { const metadataMessage: MetadataMessage = { type: MessageType.METADATA, status: StreamStatus.STARTED, completedAt: new Date().toISOString(), totalChunks: 0, fullContent: "", }; await redis.xadd(streamKey, "*", metadataMessage); await redis.publish(streamKey, { type: MessageType.METADATA }); }); const res = await context.run("generate-llm-response", async () => { const result = await new Promise<LLMStreamResponse>( async (resolve, reject) => { let fullContent = ""; let chunkIndex = 0; const { textStream } = streamText({ model: openai("gpt-4o"), prompt, onError: (err) => reject(err), onFinish: async () => { resolve({ success: true, sessionId, totalChunks: chunkIndex, fullContent, }); }, }); for await (const chunk of textStream) { if (chunk) { fullContent += chunk; chunkIndex++; const chunkMessage: ChunkMessage = { type: MessageType.CHUNK, content: chunk, }; await redis.xadd(streamKey, "*", chunkMessage); await redis.publish(streamKey, { type: MessageType.CHUNK }); } } }, ); return result; }); await context.run("mark-stream-end", async () => { const metadataMessage: MetadataMessage = { type: MessageType.METADATA, status: StreamStatus.COMPLETED, completedAt: new Date().toISOString(), totalChunks: res.totalChunks, fullContent: res.fullContent, }; await redis.xadd(streamKey, "*", metadataMessage); await redis.publish(streamKey, { type: MessageType.METADATA }); }); });Cho complete type-safety, tôi cũng viết all message schemas trong zod:
message-schema.tsimport { z } from "zod"; export const MessageType = { CHUNK: "chunk", METADATA: "metadata", EVENT: "event", ERROR: "error", } as const; export const StreamStatus = { STARTED: "started", STREAMING: "streaming", COMPLETED: "completed", ERROR: "error", } as const; export const baseMessageSchema = z.object({ type: z.enum([ MessageType.CHUNK, MessageType.METADATA, MessageType.EVENT, MessageType.ERROR, ]), }); export const chunkMessageSchema = baseMessageSchema.extend({ type: z.literal(MessageType.CHUNK), content: z.string(), }); export const metadataMessageSchema = baseMessageSchema.extend({ type: z.literal(MessageType.METADATA), status: z.enum([ StreamStatus.STARTED, StreamStatus.STREAMING, StreamStatus.COMPLETED, StreamStatus.ERROR, ]), completedAt: z.string().optional(), totalChunks: z.number().optional(), fullContent: z.string().optional(), error: z.string().optional(), }); export const eventMessageSchema = baseMessageSchema.extend({ type: z.literal(MessageType.EVENT), }); export const errorMessageSchema = baseMessageSchema.extend({ type: z.literal(MessageType.ERROR), error: z.string(), }); export const messageSchema = z.discriminatedUnion("type", [ chunkMessageSchema, metadataMessageSchema, eventMessageSchema, errorMessageSchema, ]); export type Message = z.infer<typeof messageSchema>; export type ChunkMessage = z.infer<typeof chunkMessageSchema>; export type MetadataMessage = z.infer<typeof metadataMessageSchema>; export type EventMessage = z.infer<typeof eventMessageSchema>; export type ErrorMessage = z.infer<typeof errorMessageSchema>; export const validateMessage = (data: unknown): Message | null => { const result = messageSchema.safeParse(data); return result.success ? result.data : null; };Stream Consumer
Cuối cùng, xem full stream consumer implementation. Đây là replaceable connection tự động gửi along tất cả unseen chunk khi client connect:
api/check-stream/route.tsimport { redis } from "@/utils" import { nanoid } from "nanoid" import { NextRequest, NextResponse } from "next/server" import { validateMessage, MessageType, type ErrorMessage, } from "@/lib/message-schema" export const dynamic = "force-dynamic" export const maxDuration = 60 export const runtime = "nodejs" type StreamField = string type StreamMessage = [string, StreamField[]] type StreamData = [string, StreamMessage[]] const arrToObj = (arr: StreamField[]) => { const obj: Record<string, string> = {} for (let i = 0; i < arr.length; i += 2) { obj[arr[i]] = arr[i + 1] } return obj } const json = (data: Record<string, unknown>) => { return new TextEncoder().encode(`data: ${JSON.stringify(data)}\n\n`) } export async function GET(req: NextRequest) { const { searchParams } = new URL(req.url) const sessionId = searchParams.get("sessionId") if (!sessionId) { return NextResponse.json( { error: "Stream key is required" }, { status: 400 } ) } const streamKey = `llm:stream:${sessionId}` const groupName = `sse-group-${nanoid()}` const keyExists = await redis.exists(streamKey) if (!keyExists) { return NextResponse.json( { error: "Stream does not (yet) exist" }, { status: 412 } ) } try { await redis.xgroup(streamKey, { type: "CREATE", group: groupName, id: "0", }) } catch (_err) {} const response = new Response( new ReadableStream({ async start(controller) { const readStreamMessages = async () => { const chunks = (await redis.xreadgroup( groupName, `consumer-1`, streamKey, ">" )) as StreamData[] if (chunks?.length > 0) { const [_streamKey, messages] = chunks[0] for (const [_messageId, fields] of messages) { const rawObj = arrToObj(fields) const validatedMessage = validateMessage(rawObj) if (validatedMessage) { controller.enqueue(json(validatedMessage)) } } } } await readStreamMessages() const subscription = redis.subscribe(streamKey) subscription.on("message", async () => { await readStreamMessages() }) subscription.on("error", (error) => { console.error(`SSE subscription error on ${streamKey}:`, error) const errorMessage: ErrorMessage = { type: MessageType.ERROR, error: error.message, } controller.enqueue(json(errorMessage)) controller.close() }) req.signal.addEventListener("abort", () => { console.log("Client disconnected, cleaning up subscription") subscription.unsubscribe() controller.close() }) }, }), { headers: { "Content-Type": "text/event-stream", "Cache-Control": "no-cache, no-transform", Connection: "keep-alive", }, } ) return response }Tóm Tắt Nhanh & Lời Kết
Chúng ta vừa build LLM stream cực robust handle network interruption, page refresh, thậm chí complete disconnection. Đây là gì chúng ta làm:
-
Decoupled generation từ delivery: Bằng cách tách LLM generation từ client connection, content generation tiếp tục bất kể client problem.
-
Persistent storage dùng Redis streams: Chúng ta dùng Redis streams làm persistent message broker lưu mỗi chunk của LLM response khi generated.
-
Real-time Updates với Redis Pub/Sub: Chúng ta xây notification system dùng Redis Pub/Sub notify stream consumer khi new chunk available.
-
Automatic reconnection: Client có thể reconnect bất kỳ lúc nào và tự động nhận tất cả content, guaranteed không duplicate hoặc missing chunk. Bao gồm content generated trong disconnect.
-
Session Management: Chúng ta tạo session system cho phép user xem stream trên nhiều device cùng lúc.
Bottom line, chúng ta giờ cung cấp exceptional user experience (UX). Tôi really recommend approach này, đặc biệt nếu bạn build thứ như LLM chat service.
Cheers for reading! Nếu có feedback hoặc muốn làm guest author trên Upstash, reach out at josh@upstash.com 🙌