
Trong bài này, chúng ta sẽ sử dụng PyTorch để huấn luyện một CNN nhận dạng chữ số viết tay sử dụng bộ dữ liệu MNIST.
MNIST là bộ dữ liệu phổ biến cho nhiệm vụ phân loại chữ viết tay, bao gồm hơn 70.000 hình ảnh grayscale 28x28 pixel đã được gán nhãn. Bộ dữ liệu chứa gần 60.000 ảnh huấn luyện và 10.000 ảnh kiểm tra. Nhiệm vụ của chúng ta là huấn luyện mô hình bằng 60.000 ảnh huấn luyện và kiểm tra độ chính xác phân loại trên 10.000 ảnh kiểm tra.
Cài đặt
Trước tiên chúng ta cần phiên bản mới nhất của MXNet, chạy lệnh sau trên terminal:
$pip install mxnet
Kết quả sẽ như sau:
Collecting mxnet
Downloading https://files.pythonhosted.org/packages/60/6f/071f9ef51467f9f6cd35d1ad87156a29314033bbf78ad862a338b9eaf2e6/mxnet-1.2.0-py2.py3-none-win32.whl (12.8MB)
100% |████████████████████████████████| 12.8MB 131kB/s
Requirement already satisfied: numpy in c:\python\python361\lib\site-packages (from mxnet) (1.16.0)
Collecting graphviz (from mxnet)
Downloading https://files.pythonhosted.org/packages/1f/e2/ef2581b5b86625657afd32030f90cf2717456c1d2b711ba074bf007c0f1a/graphviz-0.10.1-py2.py3-none-any.whl
….
….
Installing collected packages: graphviz, mxnet
Successfully installed graphviz-0.10.1 mxnet-1.2.0
Thứ hai, chúng ta cần thư viện torch và torchvision - nếu chưa có, cài bằng pip.
Nhập thư viện
import torch
import torchvision
Tải bộ dữ liệu MNIST
Trước khi bắt đầu chương trình, chúng ta cần bộ dữ liệu MNIST. Hãy tải hình ảnh và nhãn vào bộ nhớ và định nghĩa các siêu tham số cho thí nghiệm.
# n_epochs là số lần lặp qua toàn bộ tập huấn luyện
n_epochs = 3
batch_size_train = 64
batch_size_test = 1000

# Learning_rate và momentum cho optimizer
learning_rate = 0.01
momentum = 0.5
log_interval = 10
random_seed = 1

torch.backends.cudnn.enabled = False
torch.manual_seed(random_seed)
#
Bây giờ tải bộ dữ liệu MNIST bằng TorchVision. Chúng ta dùng batch_size 64 cho huấn luyện và 1000 cho kiểm tra. Để chuẩn hóa, dùng giá trị trung bình 0.1307 và độ lệch chuẩn 0.3081 của MNIST.
train_loader = torch.utils.data.DataLoader(
    torchvision.datasets.MNIST('/files/', train=True, download=True,
        transform=torchvision.transforms.Compose([
            torchvision.transforms.ToTensor(),
            torchvision.transforms.Normalize(
                (0.1307,), (0.3081,))
        ])
    ),
    batch_size=batch_size_train, shuffle=True)

test_loader = torch.utils.data.DataLoader(
    torchvision.datasets.MNIST('/files/', train=False, download=True,
        transform=torchvision.transforms.Compose([
            torchvision.transforms.ToTensor(),
            torchvision.transforms.Normalize(
                (0.1307,), (0.3081,))
        ])
    ),
    batch_size=batch_size_test, shuffle=True)
Kết quả
Downloading https://yann.lecun.com/exdb/mnist/train-images-idx3-ubyte.gz
Downloading https://yann.lecun.com/exdb/mnist/train-labels-idx1-ubyte.gz
Downloading https://yann.lecun.com/exdb/mnist/t10k-images-idx3-ubyte.gz
Downloading https://yann.lecun.com/exdb/mnist/t10k-labels-idx1-ubyte.gz
Processing... Done!
Sử dụng test_loader để tải dữ liệu kiểm tra
examples = enumerate(test_loader)
batch_idx, (example_data, example_targets) = next(examples)
example_data.shape
Kết quả
torch.Size([1000, 1, 28, 28])
Từ đầu ra, một batch dữ liệu kiểm tra là tensor có hình状: [1000, 1, 28, 28] nghĩa là 1000 ví dụ 28x28 pixel grayscale.
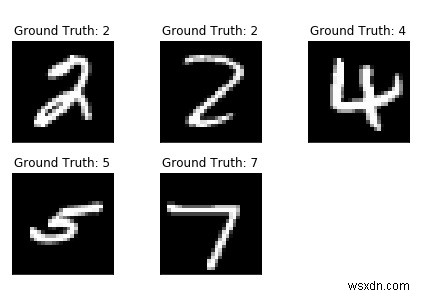
Hãy vẽ một số mẫu dữ liệu bằng matplotlib.
import matplotlib.pyplot as plt
fig = plt.figure()
for i in range(5):
    plt.subplot(2,3,i+1)
    plt.tight_layout()
    plt.imshow(example_data[i][0], cmap='gray', interpolation='none')
    plt.title("Ground Truth: {}".format(example_targets[i]))
    plt.xticks([])
    plt.yticks([])
print(fig)
Kết quả
Xây dựng mạng nơ-ron
Chúng ta sẽ xây dựng mạng với 2 lớp convolution 2D tiếp theo là 2 lớp fully-connected. Trước đó hãy nhập các module cần thiết.
import torch.nn as nn
import torch.nn.functional as F
import torch.optim as optim

class Net(nn.Module):
    def __init__(self):
        super(Net, self).__init__()
        self.conv1 = nn.Conv2d(1, 10, kernel_size=5)
        self.conv2 = nn.Conv2d(10, 20, kernel_size=5)
        self.conv2_drop = nn.Dropout2d()
        self.fc1 = nn.Linear(320, 50)
        self.fc2 = nn.Linear(50, 10)

    def forward(self, x):
        x = F.relu(F.max_pool2d(self.conv1(x), 2))
        x = F.relu(F.max_pool2d(self.conv2_drop(self.conv2(x)), 2))
        x = x.view(-1, 320)
        x = F.relu(self.fc1(x))
        x = F.dropout(x, training=self.training)
        x = self.fc2(x)
        return F.log_softmax(x)
Khởi tạo mạng và optimizer:
network = Net()
optimizer = optim.SGD(network.parameters(), lr=learning_rate, momentum=momentum)
Huấn luyện mô hình
Xây dựng vòng lặp huấn luyện. Kiểm tra mạng ở chế độ train, lặp qua toàn bộ dữ liệu huấn luyện mỗi epoch. DataLoader tải từng batch. Đặt gradient về 0 bằng optimizer.zero_grad().
train_losses = []
train_counter = []
test_losses = []
test_counter = [i*len(train_loader.dataset) for i in range(n_epochs + 1)]
Để vẽ đường cong huấn luyện, tạo 2 danh sách lưu loss huấn luyện và kiểm tra. Trục x hiển thị số ví dụ huấn luyện.
Lệnh backward() thu thập gradient mới, lan truyền ngược qua các tham số mạng bằng optimizer.step().
def train(epoch):
    network.train()
    for batch_idx, (data, target) in enumerate(train_loader):
        optimizer.zero_grad()
        output = network(data)
        loss = F.nll_loss(output, target)
        loss.backward()
        optimizer.step()
        if batch_idx % log_interval == 0:
            print('Train Epoch: {} [{}/{} ({:.0f}%)]\tLoss: {:.6f}'.format(
                epoch, batch_idx * len(data), len(train_loader.dataset),
                100. * batch_idx / len(train_loader), loss.item()))
            train_losses.append(loss.item())
            train_counter.append(
                (batch_idx*64) + ((epoch-1)*len(train_loader.dataset)))
            torch.save(network.state_dict(), '/results/model.pth')
            torch.save(optimizer.state_dict(), '/results/optimizer.pth')
Module mạng nơ-ron và optimizer có thể lưu/tải trạng thái nội bộ bằng .state_dict().
Đối với vòng lặp kiểm tra, tính tổng loss và theo dõi số chữ số phân loại đúng để tính độ chính xác.
def test():
    network.eval()
    test_loss = 0
    correct = 0
    with torch.no_grad():
        for data, target in test_loader:
            output = network(data)
            test_loss += F.nll_loss(output, target, size_average=False).item()
            pred = output.data.max(1, keepdim=True)[1]
            correct += pred.eq(target.data.view_as(pred)).sum()
    test_loss /= len(test_loader.dataset)
    test_losses.append(test_loss)
    print('\nTest set: Avg. loss: {:.4f}, Accuracy: {}/{} ({:.0f}%)\n'.format(
        test_loss, correct, len(test_loader.dataset),
        100. * correct / len(test_loader.dataset)))
Để chạy huấn luyện, thêm lời gọi test() trước khi lặp qua n_epochs để đánh giá mô hình với tham số khởi tạo ngẫu nhiên.
test()
for epoch in range(1, n_epochs + 1):
    train(epoch)
    test()
Kết quả
Test set: Avg. loss: 2.3048, Accuracy: 1063/10000 (10%)
Train Epoch: 1 [0/60000 (0%)]Loss: 2.294911
Train Epoch: 1 [640/60000 (1%)]Loss: 2.314225
...
Train Epoch: 3 [59520/60000 (99%)]Loss: 0.318569
Test set: Avg. loss: 0.0912, Accuracy: 9716/10000 (97%)
Đánh giá hiệu suất mô hình
Với chỉ 3 epoch huấn luyện, chúng ta đạt 97% độ chính xác trên tập kiểm tra. Với tham số khởi tạo ngẫu nhiên, ban đầu độ chính xác chỉ 10% trước khi huấn luyện.
Vẽ đường cong huấn luyện:
fig = plt.figure()
plt.plot(train_counter, train_losses, color='blue')
plt.scatter(test_counter, test_losses, color='red')
plt.legend(['Train Loss', 'Test Loss'], loc='upper right')
plt.xlabel('number of training examples seen')
plt.ylabel('negative log likelihood loss')
fig
Kết quả
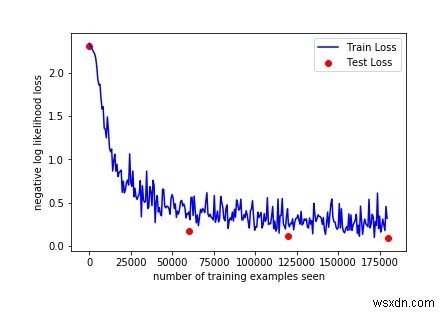
Kiểm tra đầu ra, có thể tăng số epoch để xem thêm kết quả, độ chính xác tăng qua 3 epoch.
Trước đó, chạy thêm vài ví dụ và so sánh đầu ra của mô hình:
with torch.no_grad():
    output = network(example_data)
fig = plt.figure()
for i in range(6):
    plt.subplot(2,3,i+1)
    plt.tight_layout()
    plt.imshow(example_data[i][0], cmap='gray', interpolation='none')
    plt.title("Prediction: {}".format(output.data.max(1, keepdim=True)[1][i].item()))
    plt.xticks([])
    plt.yticks([])
fig
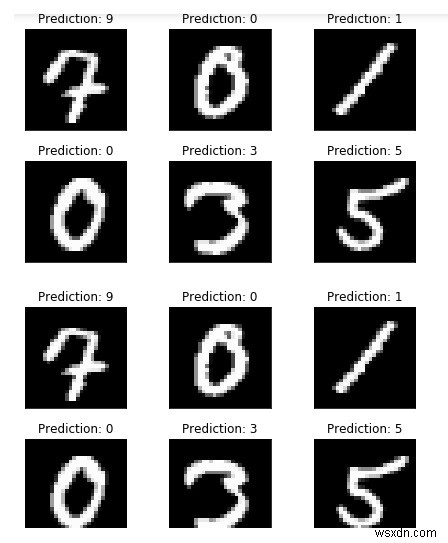
Như thấy, dự đoán của mô hình khá chính xác cho các ví dụ này.