
Chào mừng quay lại loạt bài xây dựng web scraper. Trong hướng dẫn này, tôi sẽ đi qua ví dụ scraping dữ liệu từ trang podcast của chính tôi. Sẽ trình chi tiết cách trích xuất dữ liệu, cách helper và utility methods làm việc, và cách các mảnh ghép ghép lại với nhau.
Chủ Đề
- Scraping Podcast Của Tôi
- Pry
- Scraper
- Helper Methods
- Viết Posts
Scraping Podcast Của Tôi
Hãy áp dụng những gì đã học vào thực tế. Với nhiều lý do, việc redesign cho podcast Between | Screens của tôi đã quá chậm. Có vấn đề khiến tôi muốn hét lên khi ngủ dậy. Vậy tôi quyết định setup toàn bộ static site mới, xây với Middleman và host với GitHub Pages.
Tôi đầu tư khá nhiều thời gian cho design mới sau khi tinh chỉnh Middleman blog cho phù hợp. Còn lại chỉ việc import nội dung từ Sinatra app backed by database, nên cần scrape nội dung hiện có và chuyển vào static site mới.
Làm thủ công kiểu "schmuck" hoàn toàn không trong kế hoạch—không có câu hỏi nào—vì tôi có thể nhờ bạn Nokogiri và Mechanize làm việc. Đang chờ bạn là một công việc scrape vừa nhỏ vừa không quá phức tạp nhưng có vài góc khuất thú vị, rất giáo dục cho newbie web scraping.
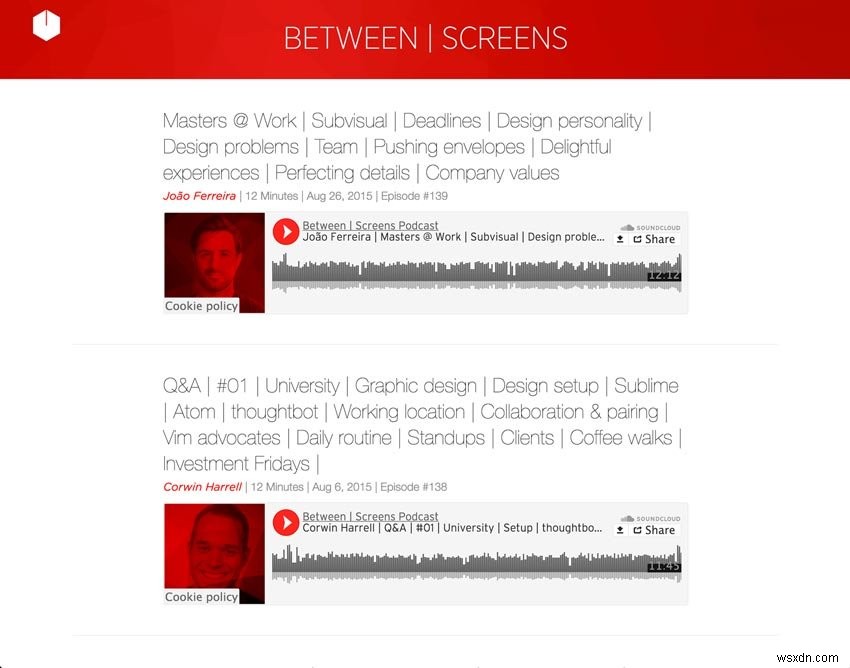
Dưới đây là hai screenshot từ podcast của tôi.
Screenshot Podcast Cũ
Screenshot Podcast Mới
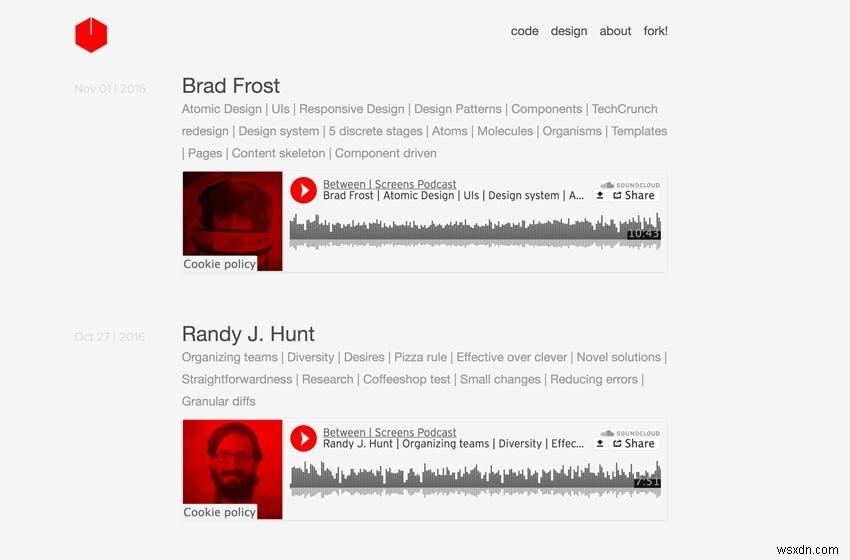
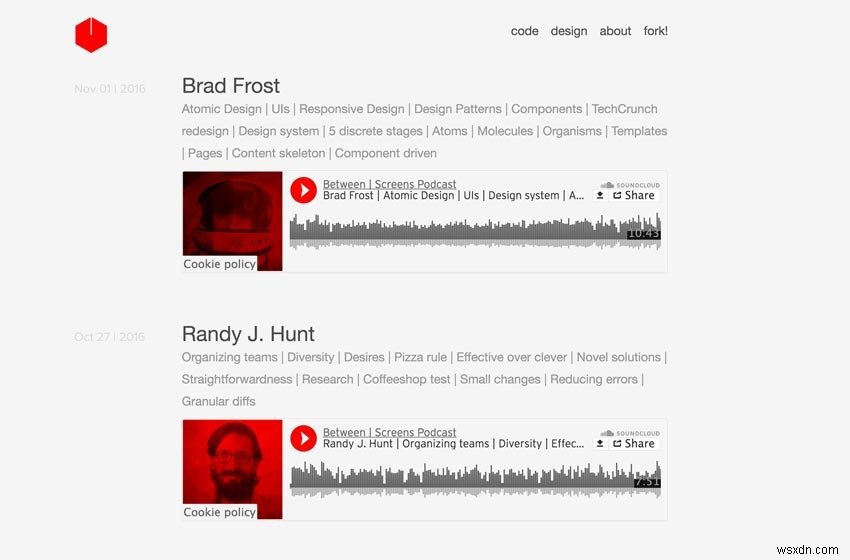
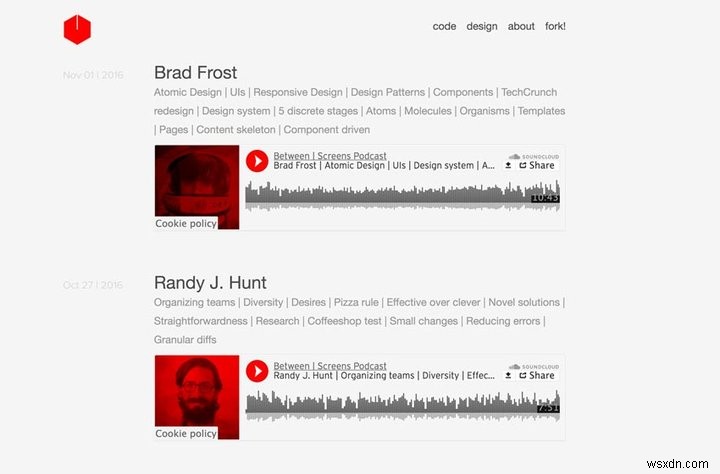
Hãy phân tích những gì muốn đạt được. Chúng ta muốn trích xuất dữ liệu sau từ 139 tập trải trên 21 trang index có phân trang:
- tiêu đề
- người được phỏng vấn
- subheader với danh sách chủ đề
- số track SoundCloud cho mỗi tập
- ngày
- số tập
- văn bản từ show notes
- link từ show notes
Lặp qua phân trang và cho Mechanize click mỗi link tập. Trên trang chi tiết sau đó, tìm tất cả thông tin cần thiết. Dùng dữ liệu scrape được, điền vào front matter và "body" của file markdown cho mỗi tập.
Dưới đây xem trước cách compose file markdown mới với nội dung trích xuất. Tôi nghĩ đây cho bạn ý tưởng về phạm vi công việc. Đây là bước cuối trong script nhỏ. Đừng lo, sẽ đi qua chi tiết.
def compose_markdown
def compose_markdown(options={})
  <<-HEREDOC
---
title: #{options[:interviewee]}
interviewee: #{options[:interviewee]}
topic_list: #{options[:title]}
tags: #{options[:tags]}
soundcloud_id: #{options[:sc_id]}
date: #{options[:date]}
episode_number: #{options[:episode_number]}
---
#{options[:text]}
HEREDOC
end
Tôi cũng muốn thêm vài thủ thuật trang cũ không làm được. Hệ thống tagging tùy chỉnh, toàn diện là quan trọng. Tôi muốn người nghe có công cụ khám phá sâu. Do đó cần tag cho mỗi người phỏng vấn và tách subheader thành tag. Vì đã sản xuất 139 tập chỉ mùa 1, phải chuẩn bị site cho lúc nội dung nhiều hơn, khó duyệt hơn. Hệ thống tagging sâu với recommendation thông minh là giải pháp. Điều này giúp site nhẹ và nhanh.
Hãy xem code hoàn chỉnh scraping nội dung site. Nhìn quanh và hiểu bức tranh toàn cảnh. Vì mong bạn ở mức beginner, tôi tránh trừu tượng hóa quá nhiều, ưu tiên rõ ràng. Tôi refactor một chút nhằm rõ ràng code, nhưng cũng để chút "thịt" để bạn tự chơi khi xong bài. Cuối cùng, học tập chất lượng xảy ra khi vượt qua đọc và tự code.
Dọc theo đường, tôi khuyến khích bạn suy nghĩ cách cải thiện code trước mắt. Đây sẽ là bài tập cuối. Gợi ý nhỏ: tách method lớn thành method nhỏ luôn là điểm khởi đầu tốt. Khi hiểu code hoạt động, bạn sẽ vui refactoring.
Tôi đã tách một đống method thành helper nhỏ, tập trung. Bạn dễ áp dụng những gì học từ bài trước về code smells và refactoring. Nếu vẫn chưa hiểu, đừng lo—chúng ta đều từng thế. Chỉ cần kiên trì, lúc nào đó mọi thứ sẽ click nhanh hơn.
Full Code
require 'Mechanize'
require 'Pry'
require 'date'

# Helper Methods
# (Extraction Methods)
def extract_interviewee(detail_page)
  interviewee_selector = '.episode_sub_title span'
  detail_page.search(interviewee_selector).text.strip
end

def extract_title(detail_page)
  title_selector = ".episode_title"
  detail_page.search(title_selector).text.gsub(/[?#]/, '')
end

def extract_soundcloud_id(detail_page)
  sc = detail_page.iframes_with(href: /soundcloud.com/).to_s
  sc.scan(/\d{3,}/).first
end

def extract_shownotes_text(detail_page)
  shownote_selector = "#shownote_container > p"
  detail_page.search(shownote_selector)
end

def extract_subtitle(detail_page)
  subheader_selector = ".episode_sub_title"
  detail_page.search(subheader_selector).text
end

def extract_episode_number(episode_subtitle)
  number = /[#]\d*/.match(episode_subtitle)
  clean_episode_number(number)
end

# (Utility Methods)
def clean_date(episode_subtitle)
  string_date = /[^|]*([,])(.....)/.match(episode_subtitle).to_s
  Date.parse(string_date)
end

def build_tags(title, interviewee)
  extracted_tags = strip_pipes(title)
  "#{interviewee}"+ ", #{extracted_tags}"
end

def strip_pipes(text)
  tags = text.tr('|', ',')
  tags = tags.gsub(/[@?#&]/, '')
  tags.gsub(/[w\/]{2}/, 'with')
end

def clean_episode_number(number)
  number.to_s.tr('#', '')
end

def dasherize(text)
  text.lstrip.rstrip.tr(' ', '-')
end

def extract_data(detail_page)
  interviewee = extract_interviewee(detail_page)
  title = extract_title(detail_page)
  sc_id = extract_soundcloud_id(detail_page)
  text = extract_shownotes_text(detail_page)
  episode_subtitle = extract_subtitle(detail_page)
  episode_number = extract_episode_number(episode_subtitle)
  date = clean_date(episode_subtitle)
  tags = build_tags(title, interviewee)
  options = {
    interviewee: interviewee,
    title: title,
    sc_id: sc_id,
    text: text,
    tags: tags,
    date: date,
    episode_number: episode_number
  }
end

def compose_markdown(options={})
  <<-HEREDOC
---
title: #{options[:interviewee]}
interviewee: #{options[:interviewee]}
topic_list: #{options[:title]}
tags: #{options[:tags]}
soundcloud_id: #{options[:sc_id]}
date: #{options[:date]}
episode_number: #{options[:episode_number]}
---
#{options[:text]}
HEREDOC
end

def write_page(link)
  detail_page = link.click
  extracted_data = extract_data(detail_page)
  markdown_text = compose_markdown(extracted_data)
  date = extracted_data[:date]
  interviewee = extracted_data[:interviewee]
  episode_number = extracted_data[:episode_number]
  File.open("#{date}-#{dasherize(interviewee)}-#{episode_number}.html.erb.md", 'w') { |file| file.write(markdown_text) }
end

def scrape
  link_range = 1
  agent ||= Mechanize.new
  until link_range == 21
    page = agent.get("https://between-screens.herokuapp.com/?page=#{link_range}")
    link_range += 1
    page.links[2..8].map do |link|
      write_page(link)
    end
  end
end

scrape
Tại sao không require "Nokogiri"? Mechanize cung cấp mọi nhu cầu scraping. Như thảo luận bài trước, Mechanize xây trên Nokogiri và cho phép trích xuất nội dung. Tuy nhiên, cover gem đó ở bài đầu quan trọng vì cần xây dựng trên nó.
Pry
Trước hết. Trước khi vào code, tôi nghĩ cần chỉ cách kiểm tra code hoạt động đúng mỗi bước. Như bạn thấy, tôi thêm công cụ khác. Trong đó, Pry rất tiện cho debugging.
Nếu đặt Pry.start(binding) bất kỳ đâu trong code, bạn có thể inspect ứng dụng chính tại điểm đó. Bạn có thể pry vào object tại điểm cụ thể. Rất hữu ích để step through app mà không bị lúng túng. Ví dụ, đặt ngay sau function write_page kiểm tra link có đúng kỳ vọng.
Pry
...
def scrape
  link_range = 1
  agent ||= Mechanize.new
  until link_range == 21
    page = agent.get("https://between-screens.herokuapp.com/?page=#{link_range}")
    link_range += 1
    page.links[2..8].map do |link|
      write_page(link)
      Pry.start(binding)
    end
  end
end
...
Chạy script, sẽ thấy như sau.
Output
»$ ruby noko_scraper.rb
321: def scrape
322: link_range = 1
323: agent ||= Mechanize.new
324:
326: until link_range == 21
327: page = agent.get("https://between-screens.herokuapp.com/?page=#{link_range}")
328: link_range += 1
329:
330: page.links[2..8].map do |link|
331: write_page(link) =>
332: Pry.start(binding)
333: end
334: end
335: end
[1] pry(main)>
Khi hỏi object link, kiểm tra xem có trên đúng track trước khi chuyển detail implement khác.
Terminal
[2] pry(main)> link
=> #<Mechanize::Page::Link "Masters @ Work | Subvisual | Deadlines | Design personality | Design problems | Team | Pushing envelopes | Delightful experiences | Perfecting details | Company values" "/episodes/139">
Trông như cần. Tuyệt, tiếp tục. Làm từng bước qua toàn app là practice quan trọng đảm bảo không bị lạc và thực sự hiểu cách hoạt động. Sẽ không cover Pry chi tiết hơn vì cần ít nhất một bài full khác. Chỉ khuyên dùng như alternative cho IRB shell tiêu chuẩn. Quay lại task chính.
Scraper
Bây giờ bạn đã quen các mảnh ghép, khuyến nghị đi qua từng cái làm rõ vài điểm thú vị. Bắt đầu với các piece trung tâm.
podcast_scraper.rb
...
def write_page(link)
  detail_page = link.click
  extracted_data = extract_data(detail_page)
  markdown_text = compose_markdown(extracted_data)
  date = extracted_data[:date]
  interviewee = extracted_data[:interviewee]
  episode_number = extracted_data[:episode_number]
  file_name = "#{date}-#{dasherize(interviewee)}-#{episode_number}.html.erb.md"
  File.open(file_name, 'w') { |file| file.write(markdown_text) }
end

def scrape
  link_range = 1
  agent ||= Mechanize.new
  until link_range == 21
    page = agent.get("https://between-screens.herokuapp.com/?page=#{link_range}")
    link_range += 1
    page.links[2..8].map do |link|
      write_page(link)
    end
  end
end
...
Trong method scrape xảy ra gì? Đầu tiên, lặp qua mọi trang index của podcast cũ. Dùng URL cũ từ Heroku app vì site mới đã online tại betweenscreens.fm. Tôi có 20 trang tập cần lặp.
Giới hạn loop qua biến link_range, cập nhật mỗi loop. Đi qua phân trang đơn giản bằng cách dùng biến này trong URL mỗi trang. Đơn giản và hiệu quả.
def scrape
page = agent.get("https://between-screens.herokuapp.com/?page=#{link_range}")
Khi nhận trang mới với 8 tập nữa để scrape, dùng page.links xác định link muốn click và follow đến trang chi tiết mỗi tập. Tôi chọn range links (links[2..8]) vì nhất quán trên mọi trang. Cách dễ nhất target link cần từ mỗi index page. Không cần lo CSS selector.
Feed link trang chi tiết cho method write_page. Đây là nơi hầu hết việc làm xảy ra. Lấy link, click, follow đến trang chi tiết bắt đầu trích xuất dữ liệu. Trên trang đó tìm tất cả thông tin cần để compose markdown episode mới cho site mới.
def write_page
extracted_data = extract_data(detail_page)
def extract_data
def extract_data(detail_page)
  interviewee = extract_interviewee(detail_page)
  title = extract_title(detail_page)
  sc_id = extract_soundcloud_id(detail_page)
  text = extract_shownotes_text(detail_page)
  episode_subtitle = extract_subtitle(detail_page)
  episode_number = extract_episode_number(episode_subtitle)
  date = clean_date(episode_subtitle)
  tags = build_tags(title, interviewee)
  options = {
    interviewee: interviewee,
    title: title,
    sc_id: sc_id,
    text: text,
    tags: tags,
    date: date,
    episode_number: episode_number
  }
end
Như thấy, lấy detail_page áp dụng một đống extraction method. Trích xuất interviewee, title, sc_id, text, episode_title, episode_number. Tôi refactor helper method tập trung phụ trách trách nhiệm trích xuất. Hãy nhìn nhanh:
Helper Methods
Extraction Methods
Tách helper này để method nhỏ hơn, encapsulate hành vi, code đọc dễ hơn. Hầu hết nhận detail_page làm argument và trích dữ liệu cụ thể cần cho Middleman posts.
def extract_interviewee(detail_page)
  interviewee_selector = '.episode_sub_title span'
  detail_page.search(interviewee_selector).text.strip
end
Tìm trang với selector cụ thể, lấy text bỏ whitespace thừa.
def extract_title(detail_page)
  title_selector = ".episode_title"
  detail_page.search(title_selector).text.gsub(/[?#]/, '')
end
Lấy title bỏ ? và # vì không chơi tốt với front matter trong post episode. Xem thêm front matter dưới.
def extract_soundcloud_id(detail_page)
  sc = detail_page.iframes_with(href: /soundcloud.com/).to_s
  sc.scan(/\d{3,}/).first
end
Ở đây cần làm chút khó hơn trích SoundCloud id cho track host. Trước cần Mechanize iframes với href của soundcloud.com biến thành string để scan...
"[#<Mechanize::Page::Frame nil \"https://w.soundcloud.com/player/?url=https%3A//api.soundcloud.com/tracks/221003494&auto_play=false&hide_related=false&show_comments=false&show_user=true&show_reposts=false&visual=true\"> ]"
Rồi match regex cho chữ số track id—soundcloud_id "221003494".
def extract_shownotes_text(detail_page)
  shownote_selector = "#shownote_container > p"
  detail_page.search(shownote_selector)
end
Trích show notes khá đơn giản. Chỉ cần tìm paragraph show notes trong trang chi tiết. Không surprise.
def extract_subtitle(detail_page)
  subheader_selector = ".episode_sub_title"
  detail_page.search(subheader_selector).text
end
Cũng tương tự subtitle, trừ là prep để trích episode number sạch từ nó.
def extract_episode_number(episode_subtitle)
  number = /[#]\d*/.match(episode_subtitle)
  clean_episode_number(number)
end
Ở đây cần regex thêm. Xem trước và sau áp dụng regex.
episode_subtitle
" João Ferreira | 12 Minutes | Aug 26, 2015 | Episode #139 "
number
"#139"
Một bước nữa đến số sạch.
def clean_episode_number(number)
  number.to_s.tr('#', '')
end
Lấy số có hash # bỏ đi. Voilà, episode number đầu tiên 139 trích được. Hãy xem utility methods khác trước khi gom lại.
Utility Methods
Sau việc trích xuất, có dọn dẹp. Có thể prep data cho compose markdown. Ví dụ, slice episode_subtitle thêm để lấy date sạch và build tags với method build_tags.
def clean_date
def clean_date(episode_subtitle)
  string_date = /[^|]*([,])(.....)/.match(episode_subtitle).to_s
  Date.parse(string_date)
end
Chạy regex khác tìm date như: " Aug 26, 2015". Nhìn chưa hữu ích. Từ string_date lấy từ subtitle, cần tạo object Date thật. Không thì vô dụng cho Middleman posts.
string_date
" Aug 26, 2015"
Lấy string đó Date.parse. Kết quả hứa hẹn hơn.
Date
2015-08-26
def build_tags
def build_tags(title, interviewee)
  extracted_tags = strip_pipes(title)
  "#{interviewee}"+ ", #{extracted_tags}"
end
Nhận title và interviewee xây dựng trong extract_data, bỏ pipe char và rác. Thay pipe bằng comma, @, ?, #, & bằng string rỗng, cuối cùng xử lý abbreviation cho with.
def strip_pipes
def strip_pipes(text)
  tags = text.tr('|', ',')
  tags = tags.gsub(/[@?#&]/, '')
  tags.gsub(/[w\/]{2}/, 'with')
end
Cuối cùng include tên interviewee vào tag list, tách tag bằng comma.
Before
"Masters @ Work | Subvisual | Deadlines | Design personality | Design problems | Team | Pushing envelopes | Delightful experiences | Perfecting details | Company values"
After
"João Ferreira, Masters Work , Subvisual , Deadlines , Design personality , Design problems , Team , Pushing envelopes , Delightful experiences , Perfecting details , Company values"
Mỗi tag sẽ thành link đến collection post cho topic đó. Tất cả xảy ra trong extract_data. Xem lại vị trí:
def extract_data
def extract_data(detail_page)
  interviewee = extract_interviewee(detail_page)
  title = extract_title(detail_page)
  sc_id = extract_soundcloud_id(detail_page)
  text = extract_shownotes_text(detail_page)
  episode_subtitle = extract_subtitle(detail_page)
  episode_number = extract_episode_number(episode_subtitle)
  date = clean_date(episode_subtitle)
  tags = build_tags(title, interviewee)
  options = {
    interviewee: interviewee,
    title: title,
    sc_id: sc_id,
    text: text,
    tags: tags,
    date: date,
    episode_number: episode_number
  }
end
Còn lại trả options hash với dữ liệu trích xuất. Feed hash này vào compose_markdown chuẩn bị data viết file cho site mới.
Viết Posts
def compose_markdown
def compose_markdown(options={})
  <<-HEREDOC
---
title: #{options[:interviewee]}
interviewee: #{options[:interviewee]}
topic_list: #{options[:title]}
tags: #{options[:tags]}
soundcloud_id: #{options[:sc_id]}
date: #{options[:date]}
episode_number: #{options[:episode_number]}
---
#{options[:text]}
HEREDOC
end
Để publish podcast episode trên Middleman site, tôi repurpose blogging system. Thay vì tạo "pure" blog post, tạo show notes cho episode hiển thị SoundCloud hosted episode qua iframe. Trên index chỉ hiển thị iframe cộng title và stuff.
Format cần thiết cho việc này gồm front matter. Cơ bản là key/value store cho static site. Thay thế nhu cầu database từ Sinatra site cũ.
Dữ liệu như tên interviewee, date, SoundCloud track id, episode number... đặt giữa ba gạch ngang (---) đầu file episode. Dưới đó là nội dung mỗi episode—câu hỏi, link, sponsor stuff...
Front Matter
---
key: value
key: value
key: value
key: value
---
Episode content goes here.
Trong method compose_markdown, dùng HEREDOC compose file với front matter cho mỗi episode lặp qua. Từ options hash feed method, trích tất cả data collect trong helper extract_data.
def compose_markdown
...
<<-HEREDOC
---
title: #{options[:interviewee]}
interviewee: #{options[:interviewee]}
topic_list: #{options[:title]}
tags: #{options[:tags]}
soundcloud_id: #{options[:sc_id]}
date: #{options[:date]}
episode_number: #{options[:episode_number]}
---
#{options[:text]}
HEREDOC
...
Đây là blueprint podcast episode mới. Chính điều chúng ta tìm. Có thể thắc mắc syntax: #{options[:interviewee]}. Interpolate như bình thường với string, nhưng vì đã trong <<-HEREDOC, bỏ double quotes.
Để định vị, vẫn trong loop, trong function write_page cho mỗi link click đến trang chi tiết show notes của episode đơn. Tiếp theo chuẩn bị viết blueprint ra file system. Tức tạo episode thực bằng filename và markdown_text vừa compose.
Bước cuối cần chuẩn bị: date, tên interviewee, episode number. Cộng markdown_text từ compose_markdown.
def write_page
...
markdown_text = compose_markdown(extracted_data)
date = extracted_data[:date]
interviewee = extracted_data[:interviewee]
episode_number = extracted_data[:episode_number]
file_name = "#{date}-#{dasherize(interviewee)}-#{episode_number}.html.erb.md"
...
Chỉ cần lấy file_name và markdown_text viết file.
def write_page
...
File.open(file_name, 'w') { |file| file.write(markdown_text) }
...
Phân tích thêm. Mỗi post cần format cụ thể: như 2016-10-25-Avdi-Grimm-120. Muốn viết file bắt đầu date, gồm tên interviewee và episode number.
Để match format Middleman expect cho post mới, lấy tên interviewee qua helper dasherize, từ Avdi Grimm thành Avdi-Grimm. Không phép màu, nhưng đáng xem:
def dasherize
def dasherize(text)
  text.lstrip.rstrip.tr(' ', '-')
end
Bỏ whitespace từ text scrape cho tên interviewee, thay space giữa Avdi và Grimm bằng dash. Phần còn lại filename ghép trong string: "date-interviewee-name-episodenumber".
def write_page
...
"#{date}-#{dasherize(interviewee)}-#{episode_number}.html.erb.md"
...
Vì nội dung trích xuất từ HTML site, không thể dùng .md hoặc .markdown làm extension. Tôi chọn .html.erb.md. Cho episode tương lai compose không scrape, bỏ phần .html.erb chỉ cần .md.
Sau bước này, loop trong function scrape kết thúc, sẽ có episode đơn trông như sau:
2014-12-01-Avdi-Grimm-1.html.erb.md
---
title: Avdi Grimm
interviewee: Avdi Grimm
topic_list: What is Rake | Origins | Jim Weirich | Common use cases | Advantages of Rake
tags: Avdi Grimm, What is Rake , Origins , Jim Weirich , Common use cases , Advantages of Rake
soundcloud_id: 179619755
date: 2014-12-01
episode_number: 1
---
Questions:
- What is Rake?
- What can you tell us about the origins of Rake?
- What can you tell us about Jim Weihrich?
- What are the most common use cases for Rake?
- What are the most notable advantages of Rake?
Links:
In">https://www.youtube.com/watch?v=2ZHJSrF52bc">In memory of the great Jim Weirich
Rake">https://github.com/jimweirich/rake">Rake on GitHub
Jim">https://github.com/jimweirich">Jim Weirich on GitHub
Basic">https://www.youtube.com/watch?v=AFPWDzHWjEY">Basic Rake talk by Jim Weirich
Power">https://www.youtube.com/watch?v=KaEqZtulOus">Power Rake talk by Jim Weirich
Learn">https://devblog.avdi.org/2014/04/30/learn-advanced-rake-in-7-episodes/">Learn advanced Rake in 7 episodes - from Avdi Grimm ( free )
Avdi">https://about.avdi.org/">Avdi Grimm
Avdi Grimm’s screencasts:
Ruby">https://www.rubytapas.com/">Ruby Tapas
Ruby">https://devchat.tv/ruby-rogues/">Ruby Rogues podcast with Avdi Grimm
Great ebook: Rake">https://www.amazon.com/Rake-Management-Essentials-Andrey-Koleshko/dp/1783280778">Rake Task Management Essentials fromhttps://twitter.com/ka8725"> Andrey Koleshko
Scraper này bắt đầu từ tập cuối, loop đến tập đầu. Demo tập 01 cũng tốt. Thấy front matter trên với data trích xuất.
Tất cả trước đó khóa trong database Sinatra app—episode number, date, tên interviewee... Giờ đã chuẩn bị cho static Middleman site mới. Phần dưới hai ba gạch ngang (---) là text show notes: câu hỏi và link phần lớn.
Final Thoughts
Xong. Podcast mới đã up và chạy. Rất vui vì dành thời gian redesign từ gốc. Publish episode mới cool hơn. Khám phá content cũng mượt hơn cho user.
Như nói trước, đây lúc bạn vào code editor vui vẻ. Lấy code này đấu tranh một chút. Tìm cách làm đơn giản hơn. Có vài cơ hội refactor code.
Tóm lại, hy vọng ví dụ nhỏ cho ý tưởng gì bạn làm được với web scraping chops mới. Tự nhiên đạt được challenge sophisticated hơn—chắc chắn có nhiều small business opportunity với skills này.
Nhưng như luôn, một bước một, đừng frustrated nếu chưa click ngay. Bình thường với hầu hết người và mong đợi. Phần của hành trình. Happy scraping!