
Một trong những framework tốt nhất để phát triển crawler là Scrapy. Scrapy là framework cào dữ liệu và thu thập web phổ biến, sử dụng chức năng cấp cao để làm cho việc cào trang web dễ dàng hơn.
Cài đặt
Cài Scrapy trên Windows dễ dàng: dùng pip hoặc conda (nếu có Anaconda). Scrapy chạy trên cả Python 2 và 3.
pip install Scrapy
Hoặc
conda install –c conda-forge scrapy
Nếu Scrapy cài đúng, lệnh scrapy sẽ có sẵn trong terminal:
C:\Users\rajesh>scrapy Scrapy 1.6.0 - no active project Usage: scrapy[options] [args] Available commands: bench Run quick benchmark test fetch Fetch a URL using the Scrapy downloader genspider Generate new spider using pre-defined templates runspider Run a self-contained spider (without creating a project) settings Get settings values shell Interactive scraping console startproject Create new project version Print Scrapy version view Open URL in browser, as seen by Scrapy [ more ] More commands available when run from project directory Use "scrapy -h" to see more info about a command.
Khởi tạo dự án
Scrapy đã cài, chạy lệnh startproject để tạo cấu trúc mặc định cho dự án Scrapy đầu tiên.
Mở terminal, điều hướng đến thư mục lưu dự án, chạy scrapy startproject
C:\Users\rajesh>scrapy startproject scrapy_example
New Scrapy project 'scrapy_example', using template directory 'c:\python\python361\lib\site-packages\scrapy\templates\project', created in: C:\Users\rajesh\scrapy_example
You can start your first spider with:
cd scrapy_example
scrapy genspider example example.com
C:\Users\rajesh>cd scrapy_example
C:\Users\rajesh\scrapy_example>tree /F
Folder PATH listing
Volume serial number is 8CD6-8D39
C:.
│ scrapy.cfg
│
└───scrapy_example
    │ items.py
    │ middlewares.py
    │ pipelines.py
    │ settings.py
    │ __init__.py
    │
    ├───spiders
    │   │ __init__.py
    │   │
    │   └───__pycache__
    └───__pycache__
Cách khác là chạy scrapy shell để cào web:
In [18]: fetch ("https://www.wsj.com/india")
2019-02-04 22:38:53 [scrapy.core.engine] DEBUG: Crawled (200) " rel="nofollow noopener noreferrer" target="_blank">https://www.wsj.com/india> (referer: None)
Crawler Scrapy trả về đối tượng "response" chứa thông tin đã tải. Kiểm tra crawler chứa gì:
In [19]: view(response)
Out[19]: True
Trên trình duyệt mặc định, link web mở và bạn thấy:
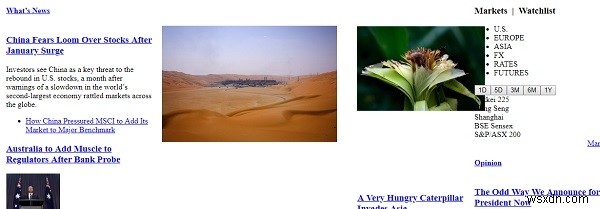
Tuyệt vời, trông giống trang web, crawler đã tải thành công toàn bộ trang.
Xem nội dung crawler:
In [22]: print(response.text)


    The Wall Street Journal & Breaking News, Business, Financial and Economic News, World News and Video


…… & so much more:
Thử trích xuất vài thông tin quan trọng từ trang web
Trích xuất tiêu đề trang web
Scrapy cung cấp cách trích xuất thông tin từ HTML dựa trên CSS selector như class, id. Để tìm CSS selector cho title, click chuột phải chọn Inspect:
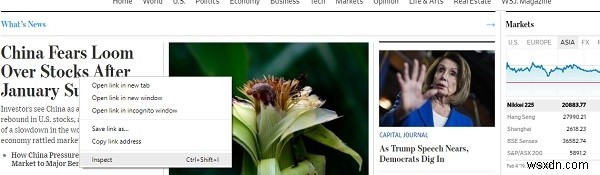
Mở developer tools:
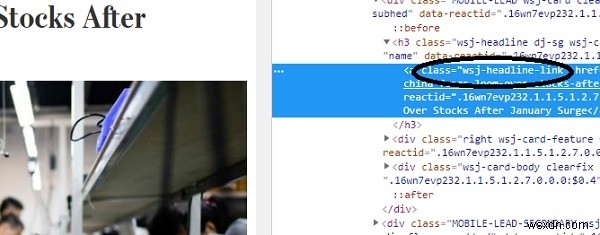
Nhìn thấy class "wsj-headline-link" áp dụng cho tất cả thẻ anchor () có tiêu đề. Dùng thông tin này để tìm tất cả tiêu đề từ nội dung còn lại trong response:
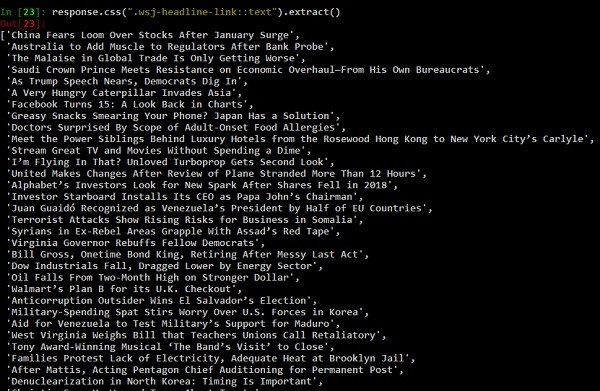
Hàm response.css() trích xuất nội dung dựa trên CSS selector (như thẻ anchor). Xem thêm ví dụ:
In [24]: response.css(".wsj-headline-link::text").extract_first()
Out[24]: 'China Fears Loom Over Stocks After January Surge'
và
In [25]: response.css(".wsj-headline-link").extract_first()
Out[25]: 'China Fears Loom Over Stocks After January Surge'
Lấy tất cả liên kết từ trang:
links = response.css('a::attr(href)').extract()
Kết quả
['https://www.google.com/intl/en_us/chrome/browser/desktop/index.html', 'https://support.apple.com/downloads/', 'https://www.mozilla.org/en-US/firefox/new/', 'https://windows.microsoft.com/en-us/internet-explorer/download-ie', 'https://www.barrons.com', 'https://bigcharts.marketwatch.com', 'https://www.wsj.com/public/page/wsj-x-marketing.html', 'https://www.dowjones.com/', 'https://global.factiva.com/factivalogin/login.asp?productname=global', 'https://www.fnlondon.com/', 'https://www.mansionglobal.com/', 'https://www.marketwatch.com', 'https://newsplus.wsj.com', 'https://privatemarkets.dowjones.com', 'https://djlogin.dowjones.com/login.asp?productname=rnc', 'https://www.wsj.com/conferences', 'https://www.wsj.com/pro/centralbanking', 'https://www.wsj.com/video/', 'https://www.wsj.com', 'https://www.bigdecisions.com/', 'https://www.businessspectator.com.au/', 'https://www.checkout51.com/?utm_source=wsj&utm_medium=digitalhousead&utm_campaign=wsjspotlight', 'https://www.harpercollins.com/', 'https://housing.com/', 'https://www.makaan.com/', 'https://nypost.com/', 'https://www.newsamerica.com/', 'https://www.proptiger.com/', 'https://www.rea-group.com/', ….. …..
Lấy số lượng bình luận từ trang WSJ:
In [38]: response.css(".wsj-comment-count::text").extract()
Out[38]: ['71', '59']
Trên chỉ là giới thiệu web scraping qua Scrapy, có thể làm nhiều hơn nữa với Scrapy.