
Rất likely bạn đã thấy Ruby exception như UndefinedConversionError hoặc IncompatibleCharacterEncodings. Less likely bạn hiểu exception nghĩa là gì. Bài này giúp. Bạn learn character encodings work và implement trong Ruby. Cuối cùng, understand và fix errors dễ hơn.
Vậy "character encoding" là gì?
Mọi programming language, work với strings. Sometimes process as input, sometimes display output. Nhưng computer không hiểu "strings". Chỉ hiểu bits: 1s và 0s. Process transform strings to bits gọi là character encoding.
Nhưng character encoding không chỉ belong computer era. Learn từ simpler process trước computers: Morse code.
Morse Code
Morse code rất simple definition. Hai symbols/ways produce signal (short và long). Với hai symbols, represent simple English alphabet. Ví dụ:
- A = .- (một short, một long)
- E = . (một short)
- O = --- (ba long)
System invented ~1837, cho phép với hai symbols, whole alphabet encoded.
Play với translator online tại đây.
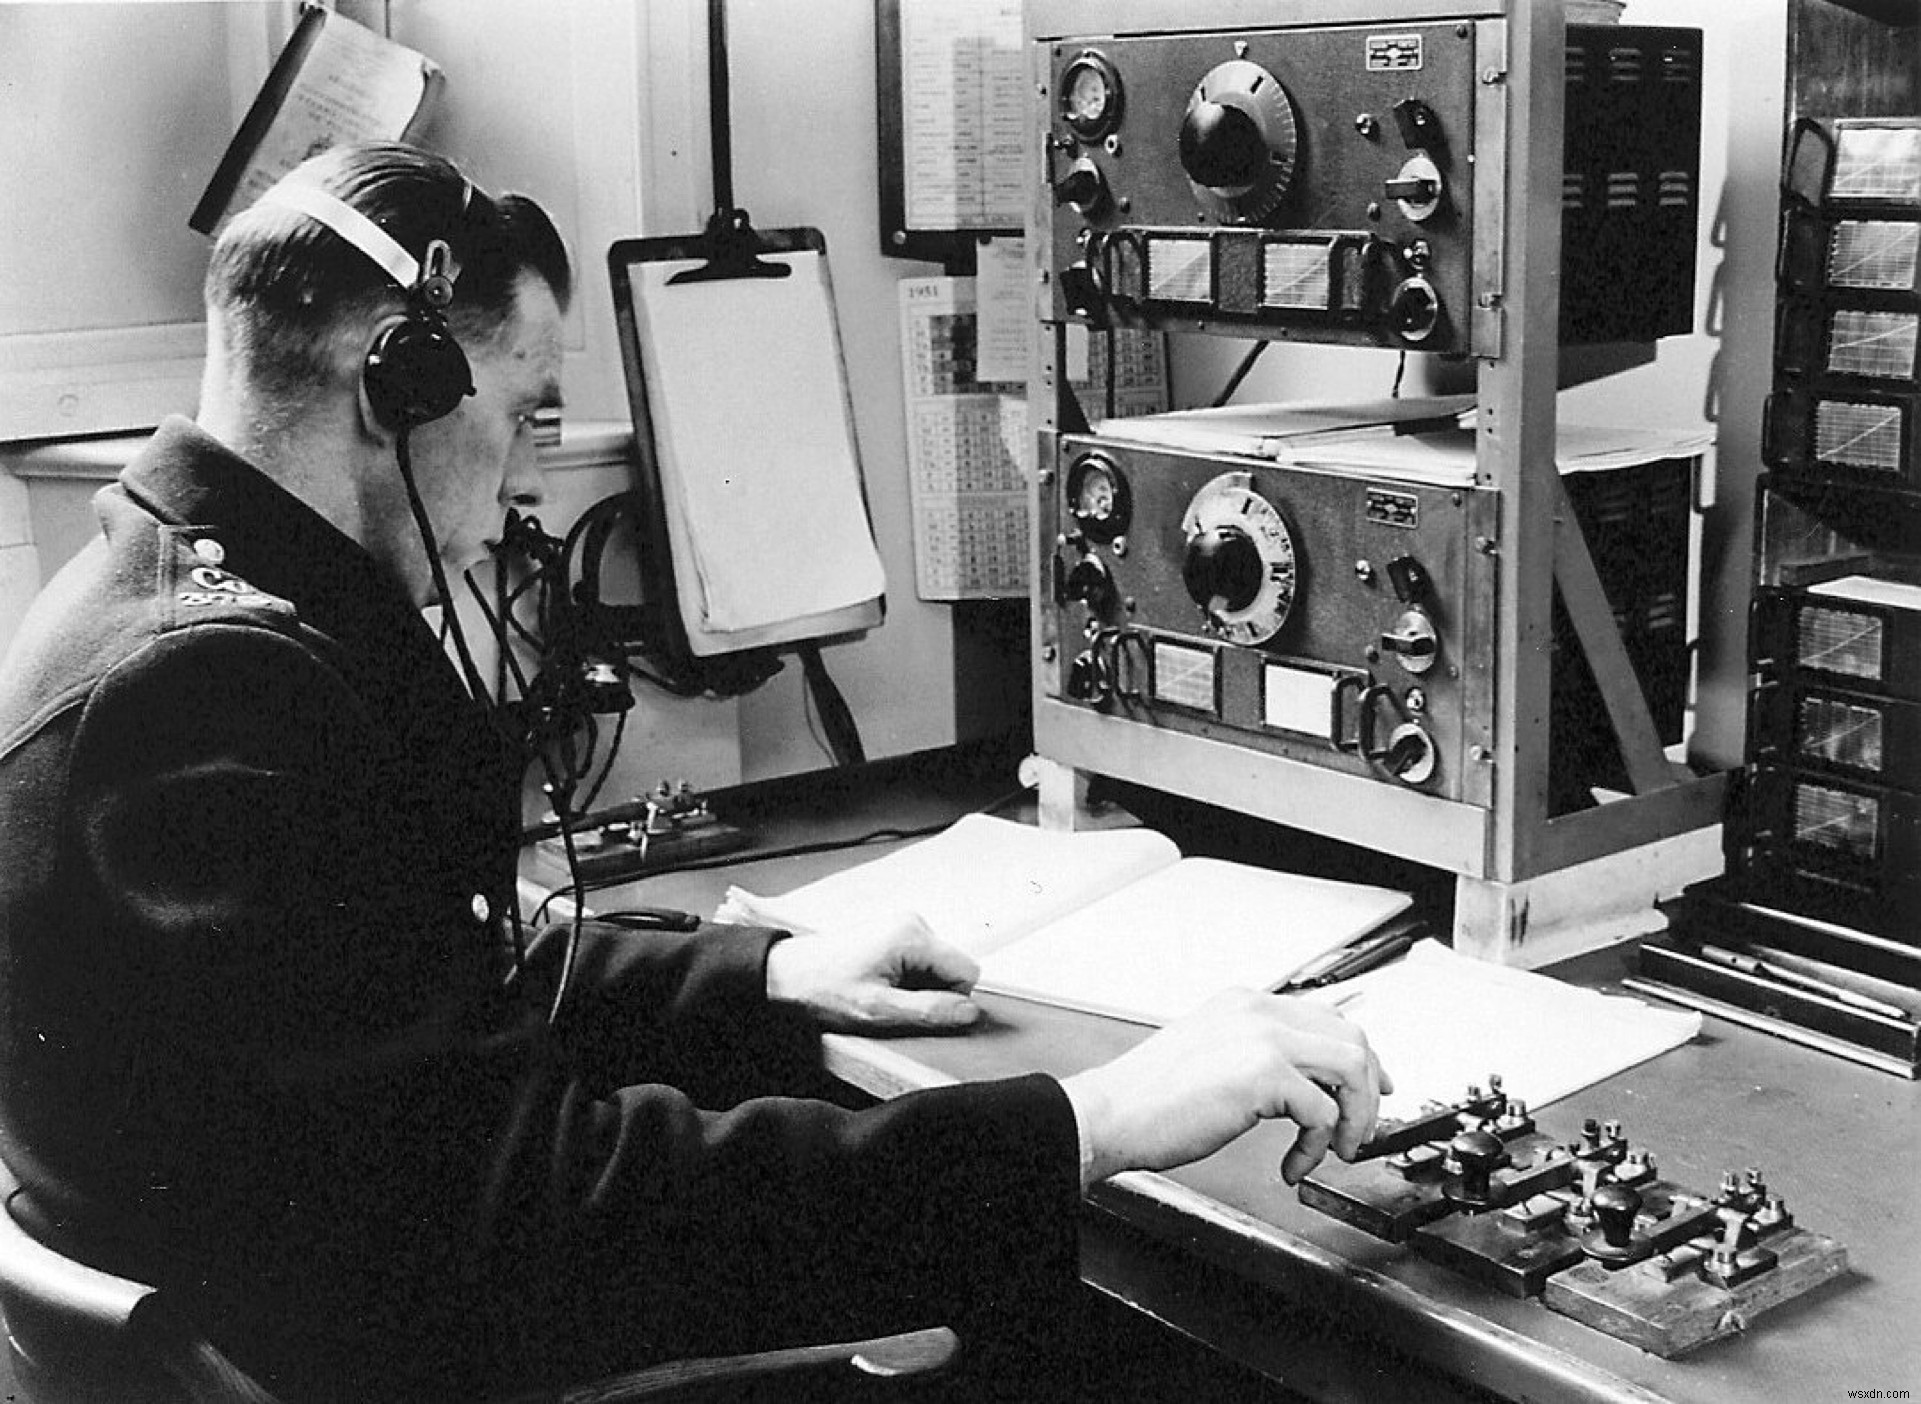
Image thấy "encoder", người responsible encode/decode messages. Sớm thay đổi với computers.
Từ Manual Đến Automatic Encoding
Encode message, cần person manually translate characters thành symbols theo Morse algorithm.
Tương tự Morse, computers dùng hai "symbols": 1 và 0. Chỉ store sequence của chúng, khi read, interpret cách make sense cho user.
Process works như sau cả hai cases:
Message → Encoding → Store/Send → Decoding → MessageSOS trong Morse:
SOS → Encode('SOS') → ...---... → Decode('...---...') → SOS
----------------------- --------------------------
Sender                  Receiver
Big change với computers: encoding/decoding automatized, không cần people translate.
Khi computers invented, early standard transform characters to 1s/0s automatically (though not first) là ASCII.
ASCII = American Standard Code for Information Interchange. "American" part played important role computers worked with information; see why next section.
ASCII (1963)
Based on telegraphic codes như Morse và very early computers, standard encoding/decoding characters in computer created ~1963. System relatively simple vì chỉ cover 127 characters, English alphabet plus extra symbols.
ASCII work bằng associate each character với decimal number translate vào binary. Example:
"A" = 65 in ASCII, translate 65 to binary.
Nếu không biết cách, quick way: Divide 65 by 2 until 0. Không exact division → add 1 remainder:
65 / 2 = 32 + 1
32 / 2 = 16 + 0
16 / 2 = 8 + 0
8 / 2 = 4 + 0
4 / 2 = 2 + 0
2 / 2 = 1 + 0
1 / 2 = 0 + 1
Take remainders inverse order:
1000001Store "A" as "1000001" original ASCII, now US-ASCII. Nowadays 8-bit computers, 01000001 (8 bits = 1 byte).
Same process each character, 7 bits store up to 2^7 = 127.
Full table:
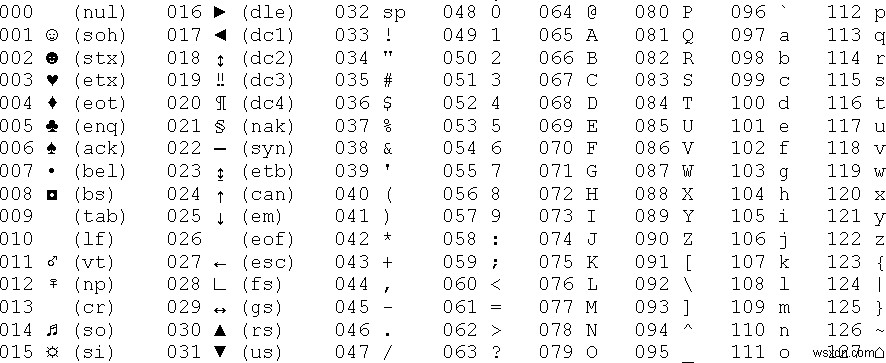 (From https://www.plcdev.com/ascii_chart)
Problem With ASCII
Muốn add character như French ç hoặc Japanese 大?
Yes, problem.
Sau ASCII, people tried solve bằng create own encoding systems. Dùng more bits, nhưng eventually caused another problem.
Main issue: reading file, không biết encoding system. Interpret với incorrect encoding → gibberish như "" hoặc "Ã,ÂÂÂÂ".
Evolution encoding systems big và wide. Depending language, different systems. Languages more characters như Chinese develop complex systems encode alphabets.
Sau nhiều years struggling, new standard: Unicode. Define cách modern computers encode/decode information.
Unicode (1988)
Unicode goal simple. Theo official site: "Provide unique number cho every character, no matter platform, program, language."
Mỗi character trong language có unique code assigned, gọi là code point. Hiện >137,000 characters.
As part Unicode standard, different ways encode values/code points, nhưng UTF-8 most extensive.
Same people tạo Go language, Rob Pike và Ken Thompson, cũng tạo UTF-8. Succeeded vì efficient và clever encode numbers. Xem tại sao.
UTF-8: Unicode Transformation Format (1993)
UTF-8 now de facto encoding websites (>94% websites). Default encoding many languages/files. Tại sao successful và how it works?
UTF-8 transform Unicode numbers to binary store in computer.
Hai aspects quan trọng: - Efficient storing bits, character 1-4 bytes. - Unicode + dynamic bytes → compatible ASCII vì first 127 chars take 1 byte. Mở ASCII file as UTF-8 OK.
Break down UTF-8 works.
UTF-8 Với 1 Byte
Depending Unicode value, UTF-8 dùng different bytes.
First 127, template: 0_______
0 always there, followed by binary Unicode value (cũng là ASCII). Example: A = 65 = 1000001.
Check Ruby với unpack method String:
'A'.unpack('B*').first # 01000001B = binary format most significant bit first. Asterisk = continue until no more bits. Dùng number → chỉ bits up to number:
'A'.unpack('B4').first # 01000UTF-8 Với 2 Bytes
Character Unicode value >127, up to 2047, dùng 2 bytes template:
110_____ 10______11 empty bits cho Unicode value. Example:
À = 192 Unicode, binary 11000000 (8 bits). Không fit template 1, dùng template 2:
110_____ 10______Fill right to left:
110___11 10000000Empty bits → 0s. Final: 11000011 10000000.
Pattern: read left to right, first 8-bit group có two 1s ở đầu → character takes 2 bytes:
11000011 10000000 --Check Ruby:
'À'.unpack('B*').first # 1100001110000000Tip: format output better:
'À'.unpack('B8 B8').join(' ') # 11000011 10000000'À'.unpack('B8 B8') return array, join với space → string. 8s trong unpack param = get 8 bits in 2 groups.
UTF-8 Với 3 Bytes
Unicode value không fit 11 bits template trước, cần extra byte:
1110____ 10______ 10______Ba 1s đầu template → 3-byte character.
Same process: transform Unicode to binary, fill right to left, empty spaces → 0s.
UTF-8 Với 4 Bytes
Values hơn 16 empty bits 3-byte template. Example emoji 🙂, Unicode cũng thấy như character "a" hoặc "大".
"🙂" code point Unicode = 128578. Binary: 11111011001000010 (17 bits). Không fit 3-byte (16 slots), cần 4-byte template:
11110___ 10______ 10______ 10______Fill binary number:
11110___ 10_11111 10011001 10000010Fill rest 0s:
11110000 10011111 10011001 10000010Ruby:
Biết 4 bytes, optimize readability:
'🙂'.unpack('B8 B8 B8 B8').join(' ') # 11110000 10011111 10011001 10000010Không biết, dùng:
'🙂'.unpack('B*')Cũng dùng "bytes" string method extract bytes to array:
"🙂".bytes # [240, 159, 153, 130]Map elements to binary:
"🙂".bytes.map {|e| e.to_s 2} # ["11110000", "10011111", "10011001", "10000010"]Muốn string, join:
"🙂".bytes.map {|e| e.to_s 2}.join(' ') # 11110000 10011111 10011001 10000010UTF-8 Có Không Gian Hơn Unicode Cần
Aspect quan trọng: UTF-8 include all Unicode values (code points) — không chỉ existing today mà cả future.
Vì 4-byte template có 21 slots → store up to 2^21 (= 2,097,152) values, way more than largest Unicode values ~1.1 million.
Confidence dùng UTF-8 không cần switch encoding future allocate new characters/languages.
Working With Different Encodings In Ruby
Ruby, see encoding string ngay:
'Hello'.encoding.name # "UTF-8"Encode string với different encoding:
encoded_string = 'hello, how are you?'.encode("ISO-8859-1", "UTF-8")
encoded_string.encoding.name # ISO-8859-1
Transformation không compatible → error by default. Convert "hello 🙂" UTF-8 to ASCII. Emoji 🙂 không fit ASCII → can't. Ruby raises error:
"hello 🙂".encode("ASCII", "UTF-8")
# Encoding::UndefinedConversionError (U+1F642 from UTF-8 to US-ASCII)
Ruby allow exceptions: character can't encode → replace "?".
"hello 🙂".encode("ASCII", "UTF-8", undef: :replace) # hello ?Option replace certain characters với valid character new encoding:
"hello 🙂".encode("ASCII", "UTF-8", fallback: {"🙂" => ":)"}) # hello :)Inspecting Script Encoding In Ruby
Xem encoding script file (.rb) đang làm việc:
__ENCODING__ # Show "#<Encoding:UTF-8>" in my caseRuby 2.0+, default encoding scripts = UTF-8, change với comment first line:
# encoding: ASCII
__ENCODING__ # #<Encoding:US-ASCII>
Better stick UTF-8 standard trừ very good reason change.
Tips Working With Encodings In Ruby
List supported encodings Ruby với Encoding.name_list. Return big array:
["ASCII-8BIT", "UTF-8", "US-ASCII", "UTF-16BE", "UTF-16LE", "UTF-32BE", "UTF-32LE", "UTF-16", "UTF-32", "UTF8-MAC"...]Aspect important working characters outside English: before Ruby 2.4, methods như upcase hoặc reverse không work as expected. Ruby 2.3 upcase không work như nghĩ:
# Ruby 2.3
'öıüëâñà'.upcase # 'öıüëâñà'
Workaround: ActiveSupport từ Rails, hoặc external gem. Từ Ruby 2.4 full Unicode case mapping:
# From Ruby 2.4+
'öıüëâñà'.upcase # 'ÖIÜËÂÑÀ'
Some Fun With Emojis
Xem emojis work Unicode và Ruby:
'🖖'.chars # ["🖖"]Đây "Raised Hand with Part Between Middle and Ring Fingers", aka "Vulcan Salute" emoji. Nếu same emoji nhưng skin tone không default, interesting happens:
'🖖🏾'.chars # ["🖖", "🏾"]Thay vì one character, hai cho single emoji.
Tại sao? Unicode characters defined as combination several characters. Case này, computer sees two characters together → show one với skin tone applied.
Another fun example flags.
'🇦🇺'.chars # ["🇦", "🇺"]Unicode, flag emojis internally represented by abstract Unicode characters "Regional Indicator Symbols" như 🇦 hoặc 🇿. Usually not used outside flags, computer sees two symbols together → show flag nếu có combination đó.
Try yourself, copy remove comma any text editor/field:
🇦,🇺Kết Luận
Hy vọng review Unicode/UTF-8 work và relate Ruby/potential errors useful.
Most important lesson: working với text có associated encoding system, important keep present khi store hoặc change. Nên dùng modern encoding như UTF-8 để không cần change future.
Note About Ruby Releases
Dùng Ruby 2.6.5 cho examples. Try online REPL hoặc local terminal irb nếu Ruby installed.
Unicode support improved recent releases, dùng latest để article stay relevant. Ruby 2.4+, all examples work as shown.