
Sử dụng requests và BeautifulSoup để thu thập nội dung trang web, làm sạch văn bản và đếm tần suất từ bằng collections.Counter.
Code hoàn chỉnh
import requests
from bs4 import BeautifulSoup
from collections import Counter

def start(url):
    wordlist = []
    source_code = requests.get(url).text
    soup = BeautifulSoup(source_code, 'html.parser')

    for each_text in soup.findAll('div', {'class': 'entry-content'}):
        content = each_text.text
        words = content.lower().split()
        for each_word in words:
            wordlist.append(each_word)
    clean_wordlist(wordlist)

def clean_wordlist(wordlist):
    clean_list = []
    symbols = '!@#$%^&*()_-+={[}]|\\;:"<>?/., '
    for word in wordlist:
        for ch in symbols:
            word = word.replace(ch, '')
        if len(word) > 0:
            clean_list.append(word)
    create_dictionary(clean_list)

def create_dictionary(clean_list):
    word_count = {}
    for word in clean_list:
        word_count[word] = word_count.get(word, 0) + 1
    c = Counter(word_count)
    top = c.most_common(10)
    print("Top 10 từ phổ biến:", top)

if __name__ == '__main__':
    start("https://www.tutorialspoint.com/python3/python_overview.htm")
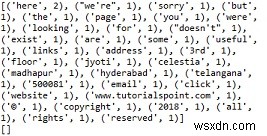
Kết quả mẫu
Cải tiến gợi ý
- Loại bỏ stop words (the, and, is...) với
nltk.corpus.stopwords. - Xử lý phân từ tốt hơn cho tiếng Việt (underscore, pyvi).
- Đa luồng để crawl nhanh hơn.
- Lưu kết quả ra CSV/JSON.