
Một vẻ đẹp của Rails framework là khả năng dùng Ruby on Rails associations trong model. Associations cho phép truy cập tập hợp record trong code với cú pháp dễ chịu, trừu tượng hóa việc viết SQL query bên dưới. Sự trừu tượng đó giữ vững miễn là data ở một nơi. Ngay khi table phân tán qua các database cluster riêng, một số association type ngừng hoạt động.
Bài này đi qua chính xác ranh giới đó và Rails cung cấp gì để làm việc trong ranh giới. Bắt đầu từ tại sao vấn đề xảy ra và association nào bị ảnh hưởng, đến cấu hình database và model hierarchy hỗ trợ multi-cluster và many-to-many relationships. Từ đó bao gồm cách các pattern truy cập dữ liệu khác nhau tương tác với phân rã đó.
Nếu tìm tutorial Rails associations cover multi-database setups, đây chính là bài đó. Cũng thảo luận nhiều điều khác, hãy đọc tiếp.
Tại sao database lại ở cluster khác nhau
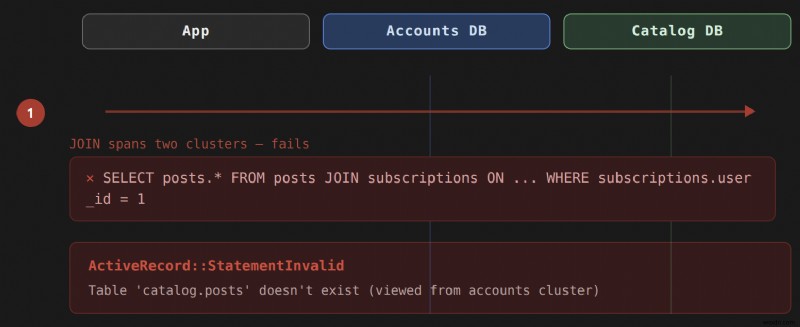
Khi Rails app lưu toàn bộ data trong single database, Active Record associations xử lý transparent, bạn không bao giờ nghĩ đến SQL bên dưới. Khi data sống qua nhiều database cluster, sự minh bạch đó sụp đổ. Một JOIN yêu cầu cả hai table tồn tại trong cùng database server. Thử JOIN cross-cluster tạo ra lỗi ActiveRecord::StatementInvalid như:
ActiveRecord::StatementInvalid (Table 'people_cluster.humans' doesn't exist) Đây không phải lỗi cấu hình. Đó là ràng buộc vật lý cứng: database server không thể JOIN đối với table chúng không host. Vấn đề này xảy ra ở has_many :through và has_one :through associations, vì đó là association type sinh intermediate JOIN queries. has_many hoặc belongs_to trực tiếp không cần join nên hoạt động cross-cluster không cần sửa đổi.
Hiểu khi bạn va chạm ranh giới là bước đầu. Nếu User ở database accounts và Post ở database content, User has_many :posts chạy tốt. Nhưng nếu thêm intermediate Subscription model ở database billing và define User has_many :posts, through: :subscriptions, Rails sẽ cố join subscriptions và posts trong single query. Đó là nơi ranh giới cluster thành vấn đề.
Cấu hình database ba tầng (three-tier)
Trước khi viết model code, cấu hình database cần phản ánh layout multi-cluster. Rails dùng cấu trúc ba tầng trong config/database.yml. Mỗi environment key top-level chứa nested database names, và mỗi cái chứa connection details cho cluster đó.
# config/database.yml default: &default adapter: postgresql pool: <%= ENV.fetch("RAILS_MAX_THREADS") { 5 } %> development: primary: <<: *default database: myapp_primary_dev accounts: <<: *default database: myapp_accounts_dev migrations_paths: db/accounts_migrate content: <<: *default database: myapp_content_dev migrations_paths: db/content_migrate production: primary: <<: *default database: myapp_primary_prod username: <%= ENV['DB_USER'] %> password: <%= ENV['DB_PASSWORD'] %> accounts: <<: *default database: myapp_accounts_prod username: <%= ENV['DB_USER'] %> password: <%= ENV['DB_PASSWORD'] %> content: <<: *default database: myapp_content_prod username: <%= ENV['DB_USER'] %> password: <%= ENV['DB_PASSWORD'] %> Key migrations_paths không optional nếu muốn Rails generators và db:migrate route migration đến đúng thư mục. Không có nó, tất cả migrations default về db/migrate áp dụng cho primary database. Mỗi secondary database cũng cần abstract record class tương ứng mà Rails models kế thừa. Generators xử lý tự động khi pass flag --database:
rails generate model Subscription plan:string --database accounts Điều này tạo class AccountsRecord nếu chưa có, và model Subscription sinh ra kế thừa từ nó.
Abstract record classes và connection routing
Abstract record classes là cơ chế Rails dùng route query đến cluster đúng. Mỗi cái gọi connects_to khai báo database map cho writing/reading. App điển hình có 3 tầng hierarchy này.
# app/models/application_record.rb class ApplicationRecord < ActiveRecord::Base self.abstract_class = true connects_to database: { writing: :primary, reading: :primary } end # app/models/accounts_record.rb class AccountsRecord < ApplicationRecord self.abstract_class = true connects_to database: { writing: :accounts, reading: :accounts } end # app/models/content_record.rb class ContentRecord < ApplicationRecord self.abstract_class = true connects_to database: { writing: :content, reading: :content } end Model User là neo hiểu hierarchy này. Nó sống trong cluster accounts kế thừa từ AccountsRecord. Model trong cluster content kế thừa ContentRecord. Còn lại kế thừa ApplicationRecord hitting primary database. Inheritance chain này là cách Active Record xác định connection pool nào dùng khi execute query. Nó đi lên class hierarchy cho đến khi tìm thấy class gọi connects_to. 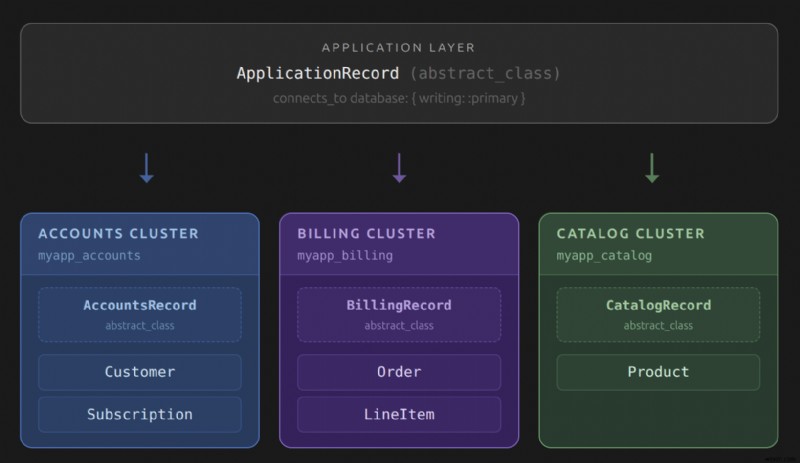
Lỗi thường gặp: gọi establish_connection trên từng model thay vì dùng abstract classes. Mỗi establish_connection mở connection pool riêng. Nếu 50 model trong database accounts mỗi cái gọi establish_connection, bạn có 50 connection pools trỏ cùng server. Abstract classes giải quyết bằng cách share single pool cho tất cả model kế thừa từ chúng.
Cross-cluster associations trong Rails thực sự hoạt động như thế nào
Option disable_joins: true là cơ chế trực tiếp làm through associations hoạt động khi table liên quan ở cluster khác. Rails has_many là association type phổ biến nhất, và bị ảnh hưởng trực tiếp bởi ranh giới cluster. Khi Rails gặp option này trên association, nó bỏ chiến lược single JOIN query và thay vào đó issue 2 (hoặc nhiều) SELECT statements tuần tự, piping IDs từ query đầu vào mệnh đề WHERE ... IN (...) trong query thứ hai.
Setup model cụ thể trải 3 clusters. Setup dưới là many-to-many relationship, User connect đến Posts through Subscriptions, pattern trực tiếp expose cross-cluster problem nhất.
# app/models/user.rb - sống trong database accounts class User < AccountsRecord has_many :subscriptions has_many :posts, through: :subscriptions, disable_joins: true end # app/models/subscription.rb - sống trong database accounts class Subscription < AccountsRecord belongs_to :user has_many :posts end # app/models/post.rb - sống trong database content class Post < ContentRecord belongs_to :subscription end Khi gọi user.posts, Rails sinh cặp query này thay vì single JOIN:
-- Query 1: fetch subscription IDs từ cluster accounts SELECT "subscriptions"."id" FROM "subscriptions" WHERE "subscriptions"."user_id" = 1 -- Query 2: fetch posts từ cluster content dùng IDs đó SELECT "posts".* FROM "posts" WHERE "posts"."subscription_id" IN (4, 7, 12) Query 1 chạy trên database accounts thu thập primary key. Query 2 chạy trên content. Rails resolve relationship bằng cách follow foreign keys, user_id trên subscriptions và subscription_id trên posts, qua 2 cluster. Query 1 thu thập primary key values từ subscriptions, pass vào mệnh đề IN của query 2. Không query nào attempt cross-cluster join. Rails lắp ráp result set cuối trong application memory. 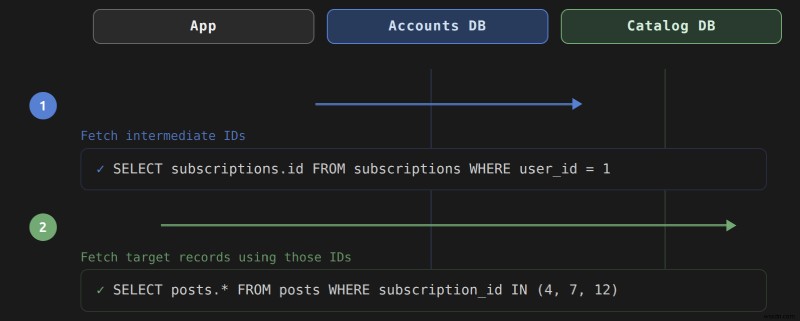
 Option tương tự hoạt động y hệt trên
has_one :through:
# app/models/user.rb class User < AccountsRecord has_one :profile has_one :avatar, through: :profile, disable_joins: true end # app/models/profile.rb - accounts database class Profile < AccountsRecord belongs_to :user has_one :avatar end # app/models/avatar.rb - content database class Avatar < ContentRecord belongs_to :profile end user.avatar thực thi 2 query: một lấy profile_id, một fetch avatar record từ cluster content.
Khi disable_joins phải set explicit
Rails không tự detect cluster boundaries chèn disable_joins cho bạn. Association loading trong Active Record là lazy. SQL cho association xác định tại điểm association định nghĩa trên model, không phải khi trigger. Lúc user.posts execute, Rails đã quyết định dùng JOIN hay separate queries dựa trên khai báo association.
Điều này nghĩa là mọi through association cross cluster boundary cần disable_joins: true trên khai báo.
Cách thực tế audit models: tìm bất kỳ through: association nào source model và target model kế thừa từ abstract record classes khác nhau. Nếu User < AccountsRecord và Post < ContentRecord, thì has_many :posts, through: :subscriptions cần disable_joins: true bất kể Subscription ở đâu.
Eager loading cross-cluster
Option disable_joins ảnh hưởng cách association load, nhưng không thay đổi cách eager loading strategies tương tác cross-cluster data. Hiểu sự khác biệt này quan trọng tránh N+1 queries trong multi-database setups.
eager_load không dùng được cho cross-cluster associations. Nó generate LEFT OUTER JOIN, cùng hạn chế vật lý như JOIN thường, cả hai table phải trên cùng server. Nếu thử User.eager_load(:posts) mà posts ở cluster khác, gặp lỗi StatementInvalid giống hệt.
preload là strategy đúng. Nó issue separate queries cho mỗi association và lắp ráp relationship trong Ruby. Cấu trúc giống hệt disable_joins làm cho single record. Khác biệt là scale: preload batch query thứ hai across tất cả parent records loaded.
# This works across clusters. # Query 1: SELECT "users".* FROM "users" # Query 2: SELECT "posts".* FROM "posts" WHERE "posts"."subscription_id" IN (...) users = User.preload(:posts).all users.each do |user| user.posts.each { |post| puts post.title } # No additional queries fired end includes chạy trong cases nó delegate to preload internally, mặc định khi không có conditions reference associated table. Nếu thêm .where clause chạm column associated table, includes switch sang eager_load behavior, fail cross-cluster. Khi nghi ngờ strategy includes chọn, hãy explicit dùng preload trực tiếp.
# includes delegates to preload here, works across clusters User.includes(:posts).all # includes switches to eager_load because of the where clause, fails across clusters User.includes(:posts).where("posts.published = ?", true) # Use preload + a separate where for cross-cluster filtering User.preload(:posts).all.select { |u| u.posts.any?(&:published?) } # Or filter in application code after loading Scoped associations và cross-cluster filtering
Một tương tác tinh tế hơn trong multi-database setups là scoped associations. Khi define scope trên has_many cross-cluster, SQL của scope chạy trên target database, không phải source.
class User < AccountsRecord has_many :subscriptions has_many :published_posts, -> { where(published: true) }, through: :subscriptions, source: :posts, class_name: "Post", disable_joins: true end Mệnh đề where(published: true) được append vào query thứ hai, query chạy trên database content. Đây là behavior đúng, nghĩa là scope có thể reference column target table không vấn đề. Điều bạn KHÔNG thể làm là reference column từ intermediate table trong scope đó, vì intermediate query đã complete khi scoped query execute.
# This will fail because subscriptions.active is not a column in the content database has_many :active_posts, -> { where("subscriptions.active = ?", true) }, through: :subscriptions, source: :posts, disable_joins: true Filter intermediate records bằng cách thêm scope vào intermediate association:
class User < AccountsRecord has_many :active_subscriptions, -> { where(active: true) }, class_name: "Subscription" has_many :active_posts, through: :active_subscriptions, source: :posts, disable_joins: true end Bây giờ filter trên subscriptions.active xảy ra trong query đầu, trên database accounts, và chỉ IDs từ active subscriptions pass sang query thứ hai.
Horizontal sharding và cross-shard associations
Chia một logical database across multiple servers dựa trên partition key như tenant_id giới thiệu chiều thứ hai cho cross-cluster problem. Cơ chế disable_joins vẫn áp dụng, nhưng connection routing phức tạp hơn.
Rails cung cấp connected_to switch giữa shards trong request:
ActiveRecord::Base.connected_to(role: :writing, shard: :shard_one) do User.find(1) # Hits shard_one end Khi associations span cả clusters và shards, cần đảm bảo cả shard context và option disable_joins có mặt. User trên shard_one truy cập posts ở database content riêng vẫn cần same two-query decomposition.
Rails 8 thêm introspection methods làm reasoning về shard topology dễ hơn runtime:
class ShardedBase < ActiveRecord::Base self.abstract_class = true connects_to shards: { shard_one: { writing: :shard_one }, shard_two: { writing: :shard_two } } end class User < ShardedBase; end User.shard_keys # => [:shard_one, :shard_two] User.sharded? # => true ShardedBase.connected_to_all_shards do User.current_shard # Yields :shard_one, then :shard_two end connected_to_all_shards đặc biệt hữu ích cho background jobs cần process records across mọi shard. Nó iterate qua từng shard lần lượt, switch connection context cho mỗi block execution.
Cho tenant-based sharding, default lock: true trên shard switching ngăn tenant hopping ngẫu nhiên mid-request. Cơ chế an toàn: once request routed đến shard của tenant, app code không switch sang shard tenant khác trừ khi explicit pass lock: false. Cross-cluster associations trong single tenant's shard vẫn dùng disable_joins cho associations chạm database cluster khác.
Testing cross-cluster associations
Test multi-database setups yêu cầu test environment mirror production database topology. Rails test framework hỗ trợ nhưng cấu hình phải explicit.
Mỗi database trong database.yml cần block environment test. Fixtures và factory-based test data phải target đúng database. Nếu User factory tạo record trong database accounts và Post factory tạo trong content, association giữa chúng chỉ chạy nếu cả hai record tồn tại trong respective databases trong cùng test transaction.
Rails wrap mỗi test trong transaction mặc định, nhưng transaction là per-connection. Với multiple databases, mỗi connection có transaction riêng. Nghĩa là test cleanup (auto rollback cuối test) xảy ra độc lập trên mỗi database. Nếu test ghi User vào accounts và Post vào content, cả hai rollback, nhưng chỉ nếu test framework biết về cả hai connections.
Khai báo fixtures xử lý tự động khi models kế thừa đúng abstract class. Cho factory-based setups (FactoryBot, Fabricator), đảm bảo factory create strategy hit đúng database bằng cách để model's own connects_to routing làm việc.
# spec/factories/users.rb FactoryBot.define do factory :user do # User inherits from AccountsRecord and writes to accounts DB automatically name { Faker::Name.name } end end # spec/factories/posts.rb FactoryBot.define do factory :post do # Post inherits from ContentRecord and writes to content DB automatically association :subscription title { Faker::Lorem.sentence } end end Để verify cross-cluster associations fire expected query count, subscribe to notification sql.active_record:
# spec/support/query_counter.rb module QueryCounter def assert_query_count(expected, &block) count = 0 callback = ->(_name, _start, _finish, _id, payload) do count += 1 unless payload[:name] == "SCHEMA" || payload[:sql].start_with?("EXPLAIN") end ActiveSupport::Notifications.subscribed(callback, "sql.active_record", &block) assert_equal expected, count, "Expected #{expected} queries, got #{count}" end end Một has_many :through với disable_joins: true trên single record nên produce exactly 2 queries. Nếu thấy 1, join vẫn đang attempt (sẽ fail production trên separate servers). Nếu thấy N+1, eager loading không chạy như mong đợi.
Một số lưu ý (caveats)
disable_joins giải quyết association loading problem, nhưng không extend đến query chaining. Bạn KHÔNG thể chain .where, .order, .group clauses reference columns cross-cluster trên single Active Record relation:
# This does not work, you cannot filter products by order columns across clusters customer.purchased_products.where("orders.total > ?", 100) Cho query cần filter/sort dựa trên data multiple clusters, decompose thủ công. Fetch IDs/values cần từ cluster này, dùng làm input query cluster kia:
high_value_order_ids = Order.where(customer_id: customer.id) .where("total > ?", 100) .pluck(:id) line_item_product_ids = LineItem.where(order_id: high_value_order_ids).pluck(:product_id) products = Product.where(id: line_item_product_ids) Đây là decomposition giống disable_joins làm internally, nhưng explicit để bạn apply filtering mỗi stage. Verbose hơn, nhưng làm ranh giới cluster visible trong code thay vì ẩn sau Rails associations syntax.
Editor's note: Bài gốc publish tháng 1/2023, updated cho accuracy.